TensorNova
Enterprise-grade server platforms, high-speed interfaces, and computing accelerators designed for latency-critical deep learning and big data systems.
Analyzing the global trade pathways, computing hardware demands, and supply chain strategies driving today's AI and data center deployment.
In the contemporary digital economy, application performance is no longer just a metric of software efficiency; it is heavily dictated by the underlying hardware architecture, storage configurations, and computing fabrics. The global compute industry is experiencing an unprecedented surge in demand, propelled by large language models (LLMs) like DeepSeek, high-performance computing (HPC) research, and complex enterprise resource planning (ERP) consolidation. Data centers globally are migrating from traditional CPU-centric architectures to highly accelerated heterogeneous GPU servers to satisfy these computational workloads.
As export compliance frameworks tighten and hardware supply lines become more complex, top manufacturers in the Asia-Pacific region, particularly in hub regions like Shenzhen, China, have optimized their logistical footprints. Global supply networks ensure that servers equipped with cutting-edge Intel Xeon processors, high-bandwidth DDR5 RAM, and high-density SSD arrays are assembled, validated, and shipped directly to core infrastructure markets across North America, Europe, Singapore, and the Middle East. Reliability and energy efficiency are the focal points of modern server manufacturing, driving the adoption of liquid-cooling pathways and modular server boards that minimize downtime.
Manufacturers are leveraging strategic export pipelines from high-tech manufacturing corridors like Shenzhen. By partnering with global component suppliers, hardware brands guarantee short lead times and cross-border regulatory compliance for data hubs in Europe, the United States, and the UAE.
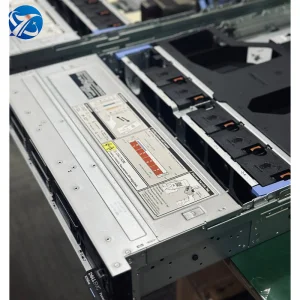
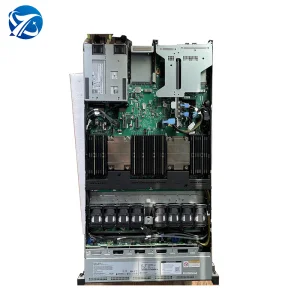
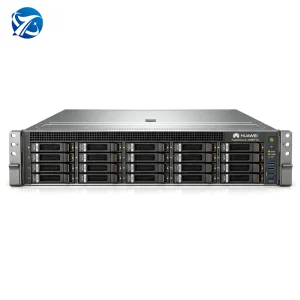
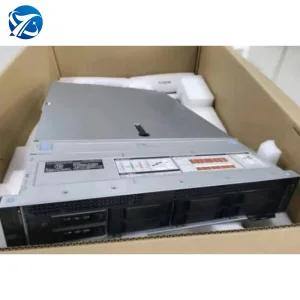
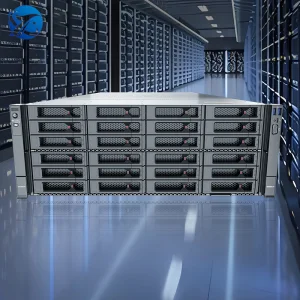
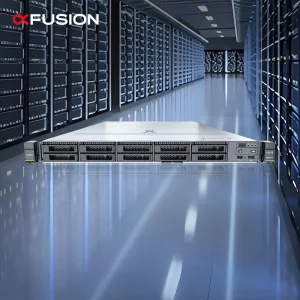
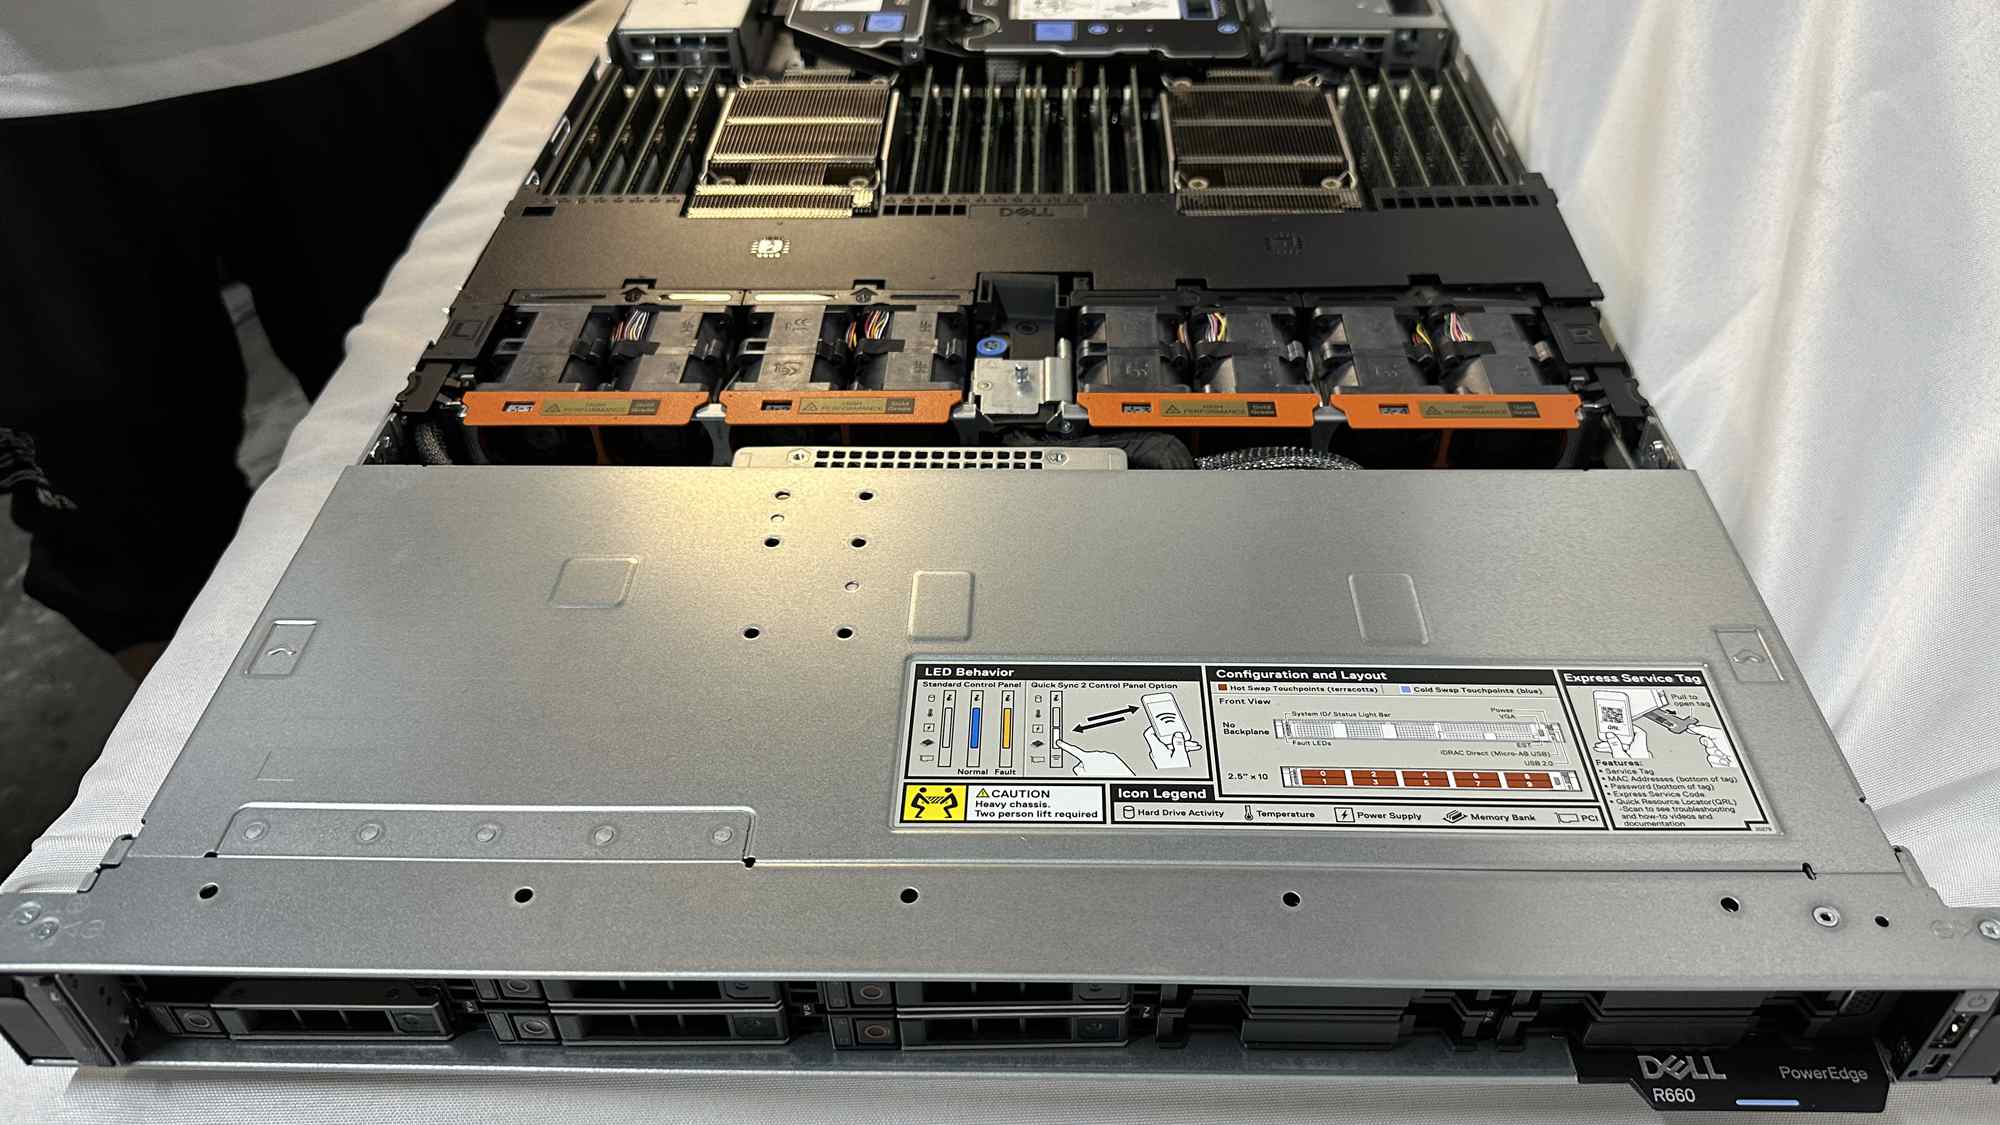
Standard servers are being upgraded to accommodate multi-GPU platforms. High-density 1U and 2U server systems optimize spatial footprints in multi-tenant data centers while maximizing thermal capabilities for workloads such as AI model training and inferencing.
How next-generation computing systems bypass memory bottlenecks and optimize interconnect performance for high-throughput AI workloads.
The architecture of high-performance computing centers is shifting rapidly due to several key engineering developments:
These advancements have driven hardware providers to focus on system-level integration rather than individual component assembly. This shift ensures compatibility with modern orchestration engines such as Kubernetes, OpenStack, and containerized AI training frameworks.
A comprehensive overview of TensorNova's manufacturing capabilities, quality assurance protocols, and global hardware delivery infrastructure.
TensorNova is a professional high-performance AI GPU server manufacturer and infrastructure solution provider based in China. The company specializes in delivering high-density AI computing nodes, GPU clusters, and scalable, customized data center hardware solutions engineered for global enterprises. Established in 2016, TensorNova has grown into a trusted hardware partner in the AI infrastructure industry, prioritizing performance, engineering reliability, and customized board-level computing setups.
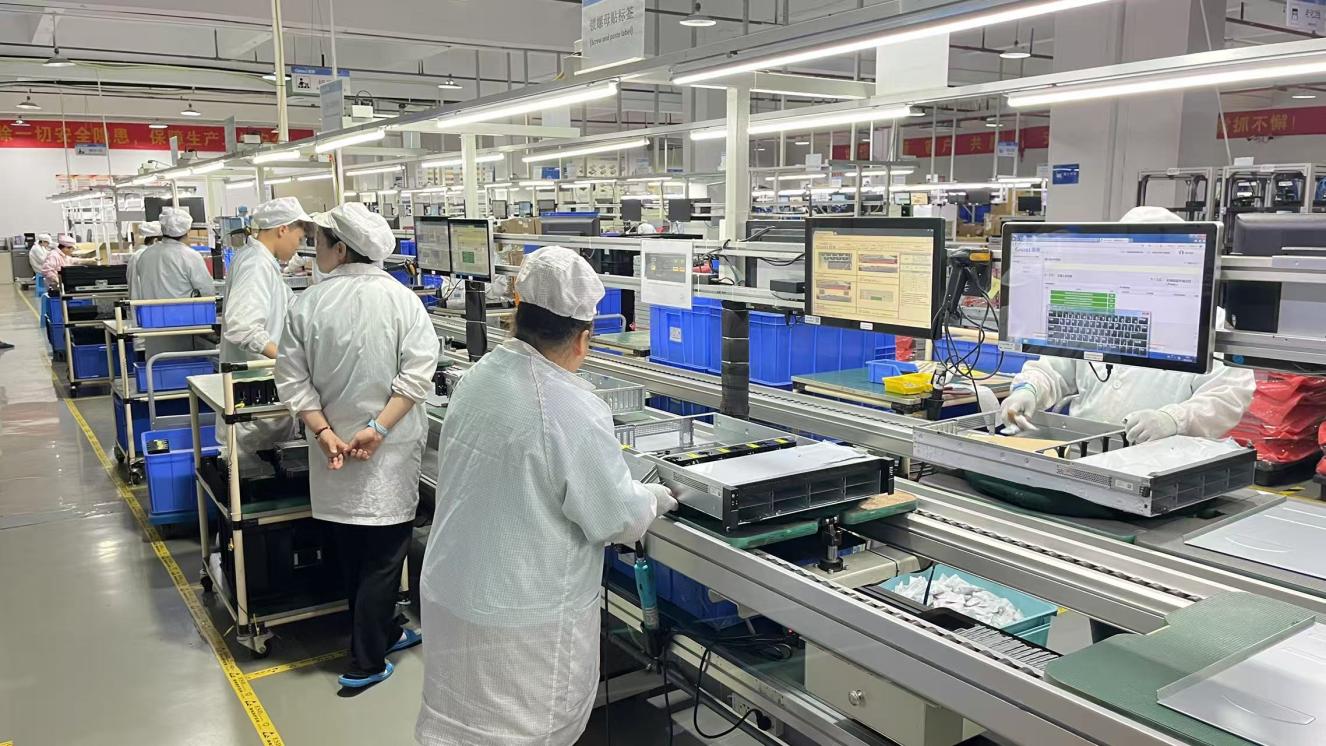
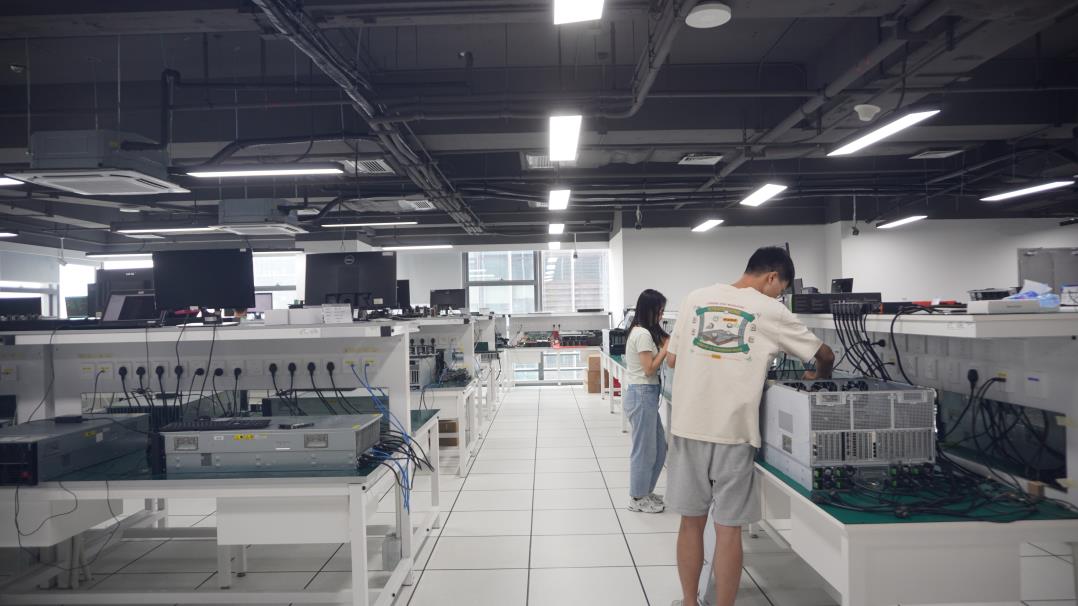
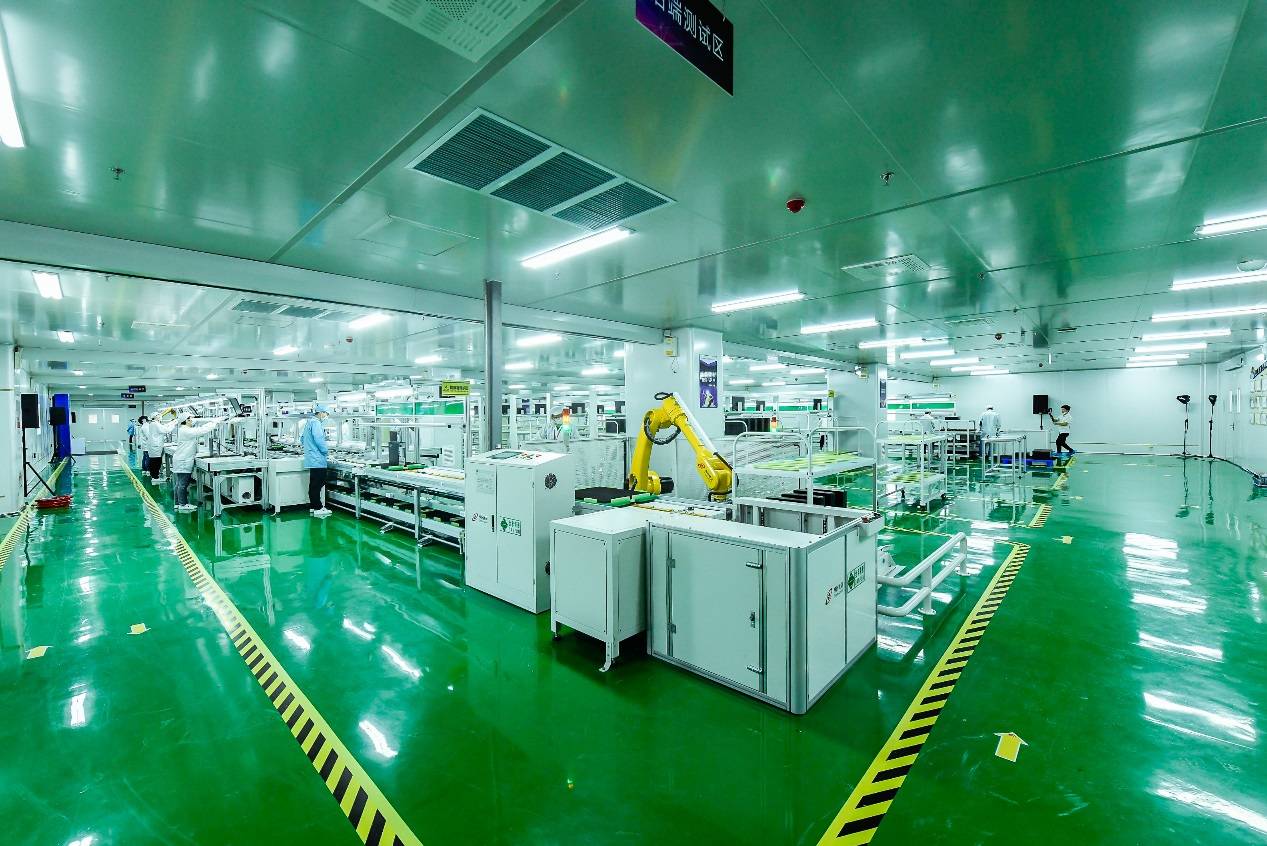
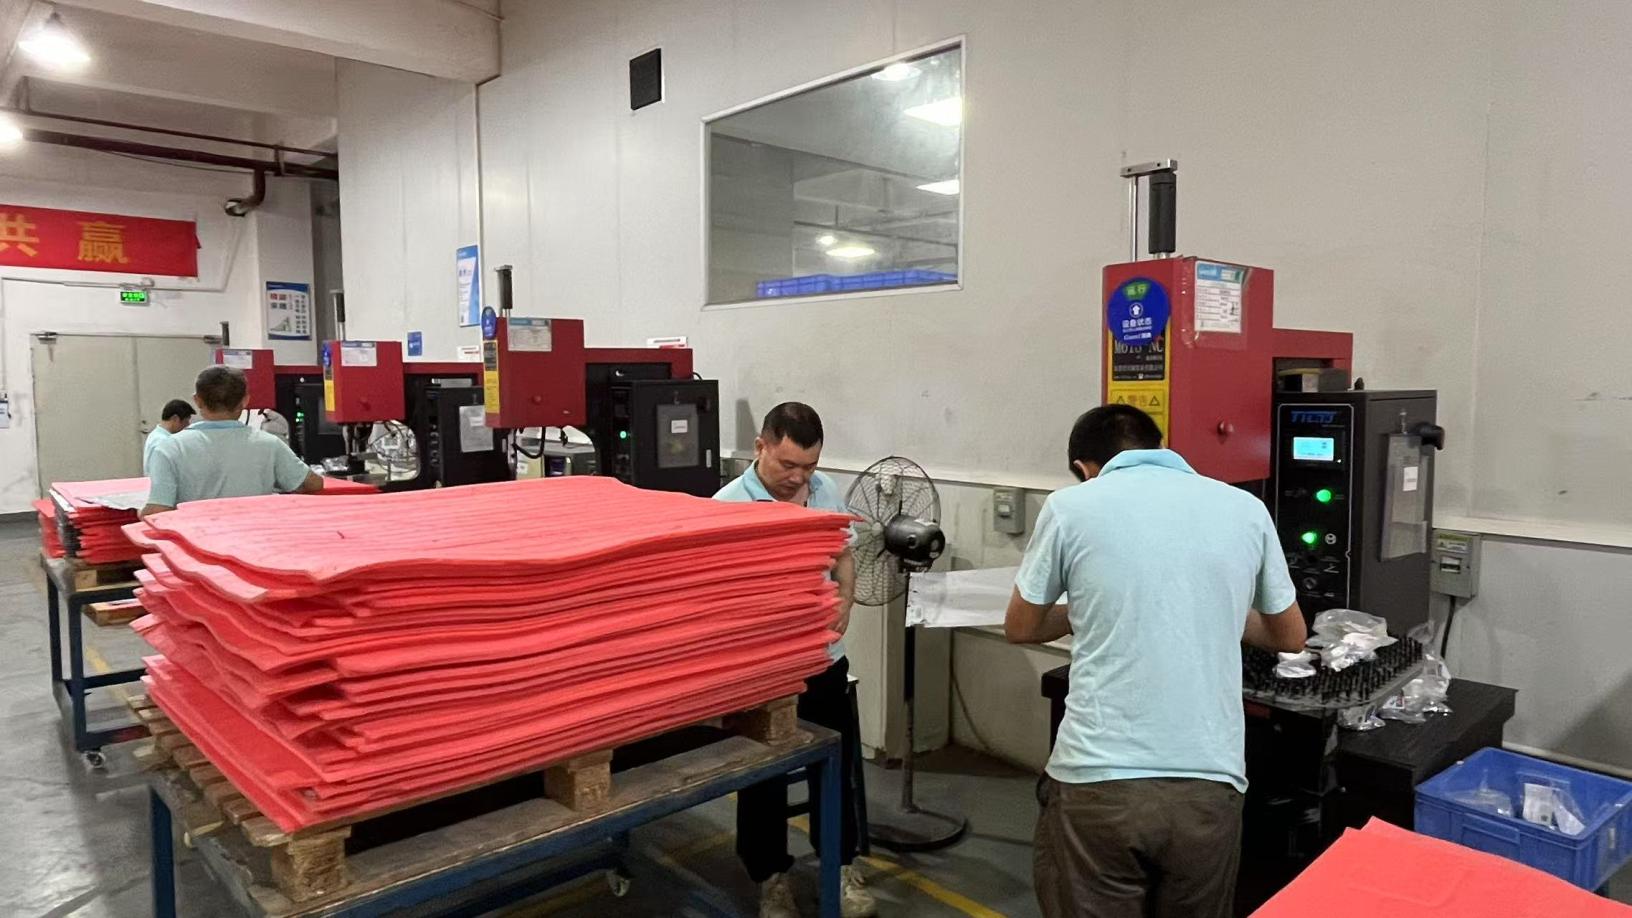
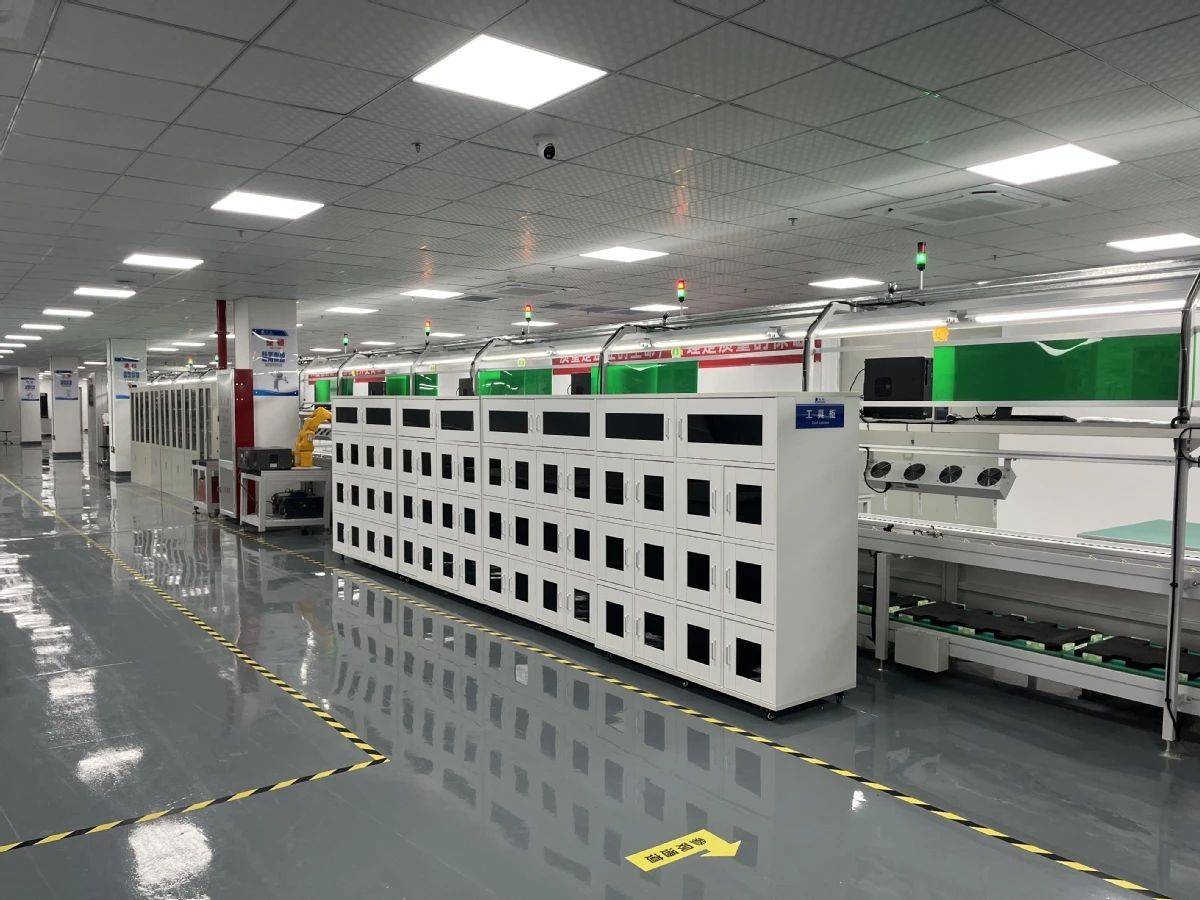
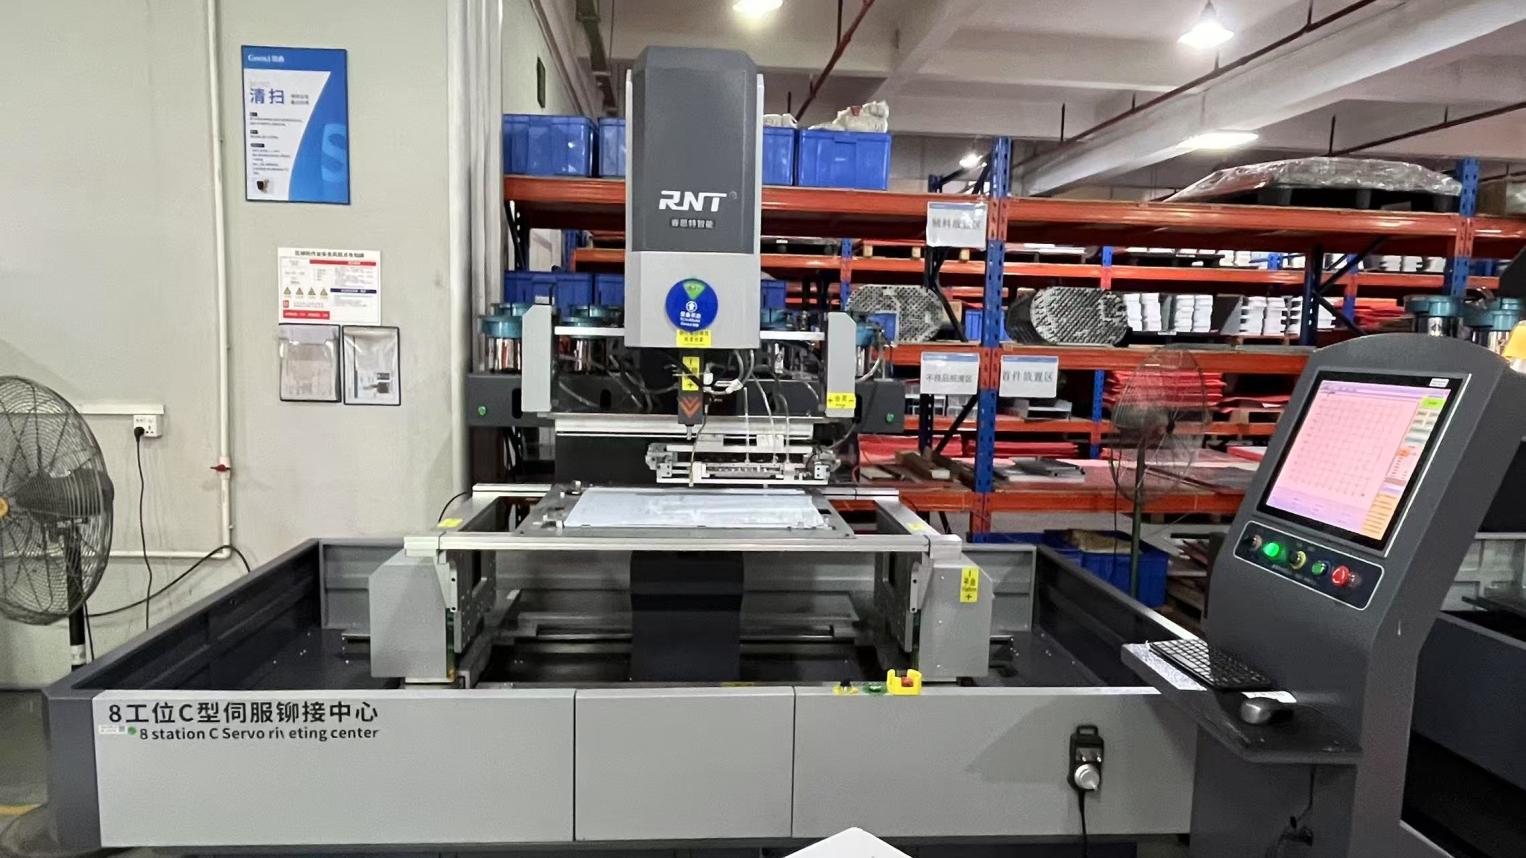
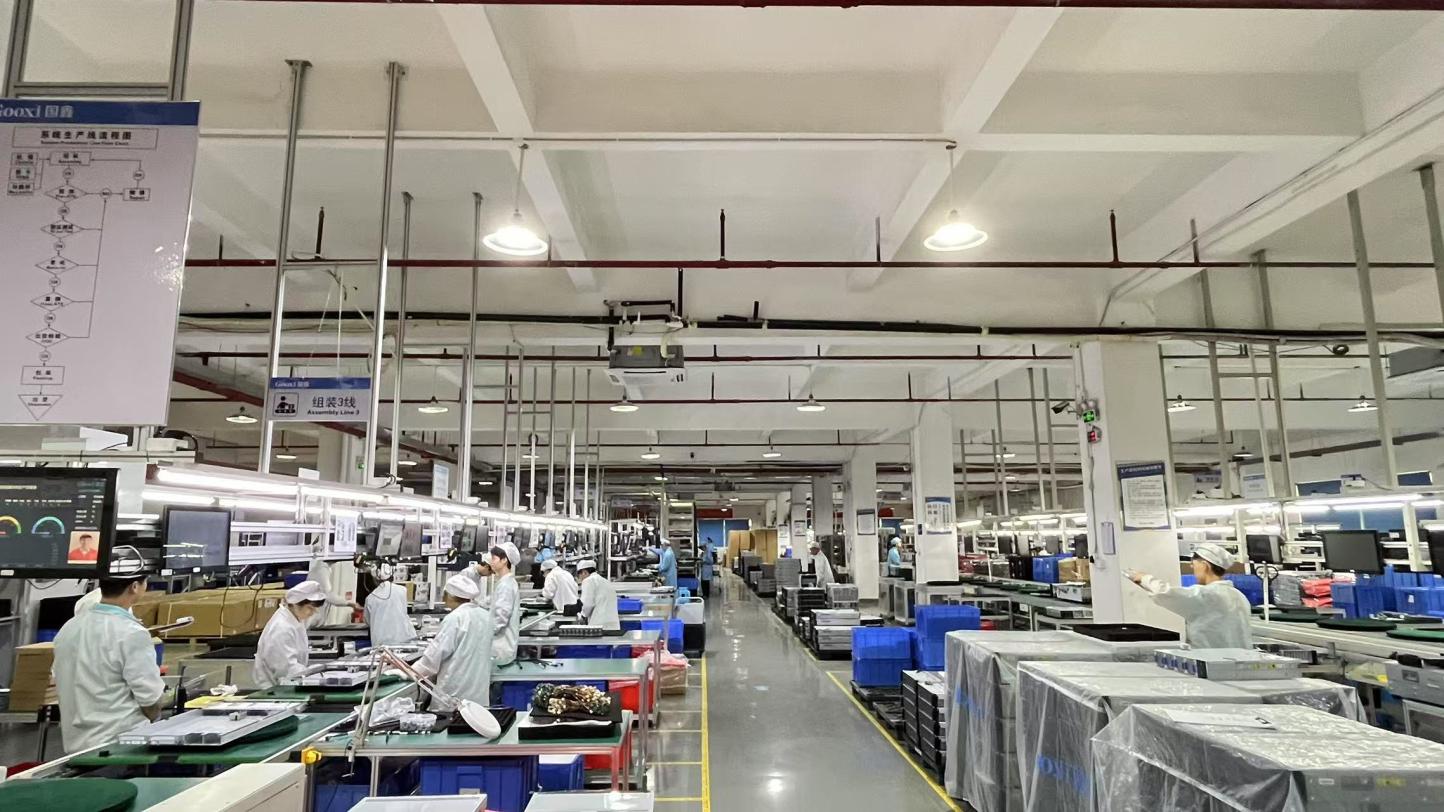
Operating out of a modern, specialized production facility covering approximately 320㎡, TensorNova streamlines server assembly, hardware optimization, component burn-in, and full system integration. Every server node produced is subjected to strict ISO9001-based quality management systems. The quality assurance pipeline features advanced automated hardware stress testing, thermal chamber performance validation, system burn-in testing, and simulated AI workload environments to verify compute stability.
Backed by a strong international trade background, TensorNova serves enterprise customers across North America, Europe, Southeast Asia, and the Middle East, with major markets in the United States, Germany, Singapore, and the United Arab Emirates. Over the last year, their engineering teams have launched more than 320 new products, including next-generation edge compute modules, container-ready deep learning systems, and liquid-cooled multi-GPU clusters. TensorNova offers extensive custom builds, including specialized motherboard-level tuning, tailormade chassis configurations, and custom cooling system layouts (both advanced air and closed-loop liquid cooling) to meet specialized application performance requirements.
An authoritative analysis of future server design, component standardization, and cooling methodologies designed to handle exponential data scaling.
The continuous scaling of artificial intelligence models requires key architectural updates for the next generation of server systems:
To overcome the classic Von Neumann bottleneck, modern servers are transitioning to PCIe Gen6 architectures. This update doubles the data transfer speeds of standard motherboard slots. This technology, combined with high-density interconnect cables, allows real-time communication between NVMe storage arrays and multi-GPU setups.
As processor TDPs (Thermal Design Power) exceed 350W per socket and GPU chips approach 700W+, standard air cooling is reaching its physical limits. Next-generation server motherboards are designed with direct-to-chip water block mounts. This configuration helps reduce fan power consumption in data centers by up to 40%.
Compute Express Link (CXL) technology allows servers to share memory resources (like DDR5 RDIMMs) across computing nodes in a single rack. This strategy prevents compute bottlenecks, reduces overall DRAM idle capacity, and improves hardware utilization rates across virtualized cloud environments.
Examining deployment architectures in mission-critical environments, from local ERP networks to distributed AI computing systems.
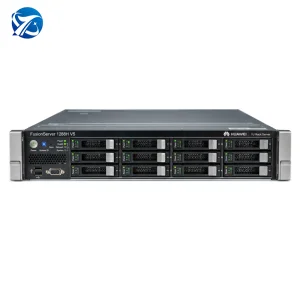
Large companies running complex database instances, global logistics trackers, and ERP platforms (like SAP Hana or Oracle EBS) require high-density, multi-socket server layouts. Utilizing 4-socket configurations like the FusionServer 2488H V5 ensures maximum uptime, dense memory pooling (using multi-channel DDR4/DDR5 systems), and hardware partitioning. This allows multiple operations to run concurrently without performance degradation.
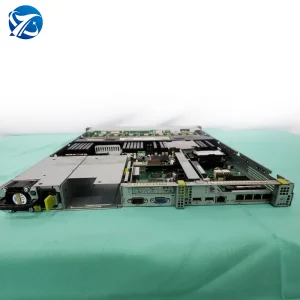
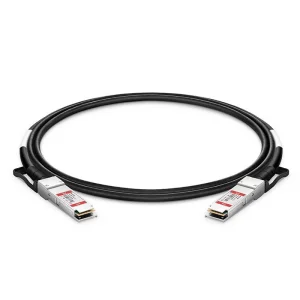
AI laboratories and commercial cloud providers deploy dedicated GPU acceleration nodes like the FusionServer G5500 V7. Combined with high-speed direct-attach QSFP+ cabling, these setups deliver the memory throughput and tensor calculations required to train and run models like DeepSeek. Specialized board designs optimize power delivery to GPU modules, ensuring system reliability during long computational tasks.
Hosting providers and content delivery networks (CDNs) require high-density, web-accessible storage nodes. Dual-socket 1U and 2U options like the xFusion 1288H V6 and Dell R760XD2 provide a balanced configuration of PCIe NVMe expansion slots, SAS/SATA hot-swap storage bays, and redundant Power Supply Units (PSUs). This ensures data availability and low latency for edge deployments.
Small and medium enterprises (SMEs) require compact, cost-efficient rack server options that do not demand complex liquid cooling systems. 1U systems like the PowerEdge R260 and R360 act as firewalls, local network attached storage (NAS) managers, domain controllers, and virtualization nodes, bringing server-class reliability to smaller office operations.
Expert insights addressing key server selection questions, thermal management strategies, and hardware optimization tips for IT managers.
Enterprise server components, redundant multi-socket platforms, and memory expansion kits designed to improve overall application throughput.