TensorNova
Deploy scalable, mission-critical OEM/ODM server architecture engineered for zero-data-loss target applications and instant failover recovery.
In an era dominated by hyper-converged compute nodes, distributed multi-cloud topologies, and high-density Artificial Intelligence workloads, data center resilience has evolved from a passive fallback safeguard into a core strategic differentiator. Global industry reports estimate that enterprise downtime costs now exceed $9,000 per minute for mission-critical operations across financial services, telecom backbones, healthcare grids, and sovereign AI data centers.
As sophisticated cybersecurity threats like ransomware evolve alongside physical disruption risks, enterprise IT directors are demanding advanced OEM/ODM Disaster Recovery solutions. These solutions must enforce rigorous Recovery Time Objectives (RTO approaching real-time) and Recovery Point Objectives (RPO near zero). Standard off-the-shelf server configurations often lack the specialized controller redundancy, customizable hardware-level failover protocols, and low-latency storage tiering required to maintain business continuity during catastrophic node outages.
Delivering world-class compute nodes, storage systems, and specialized hardware customized for global enterprise resilience.
TensorNova is a professional high-performance AI GPU server manufacturer and infrastructure solution provider based in China, specializing in AI computing, GPU clusters, and scalable data center hardware solutions for global enterprises.
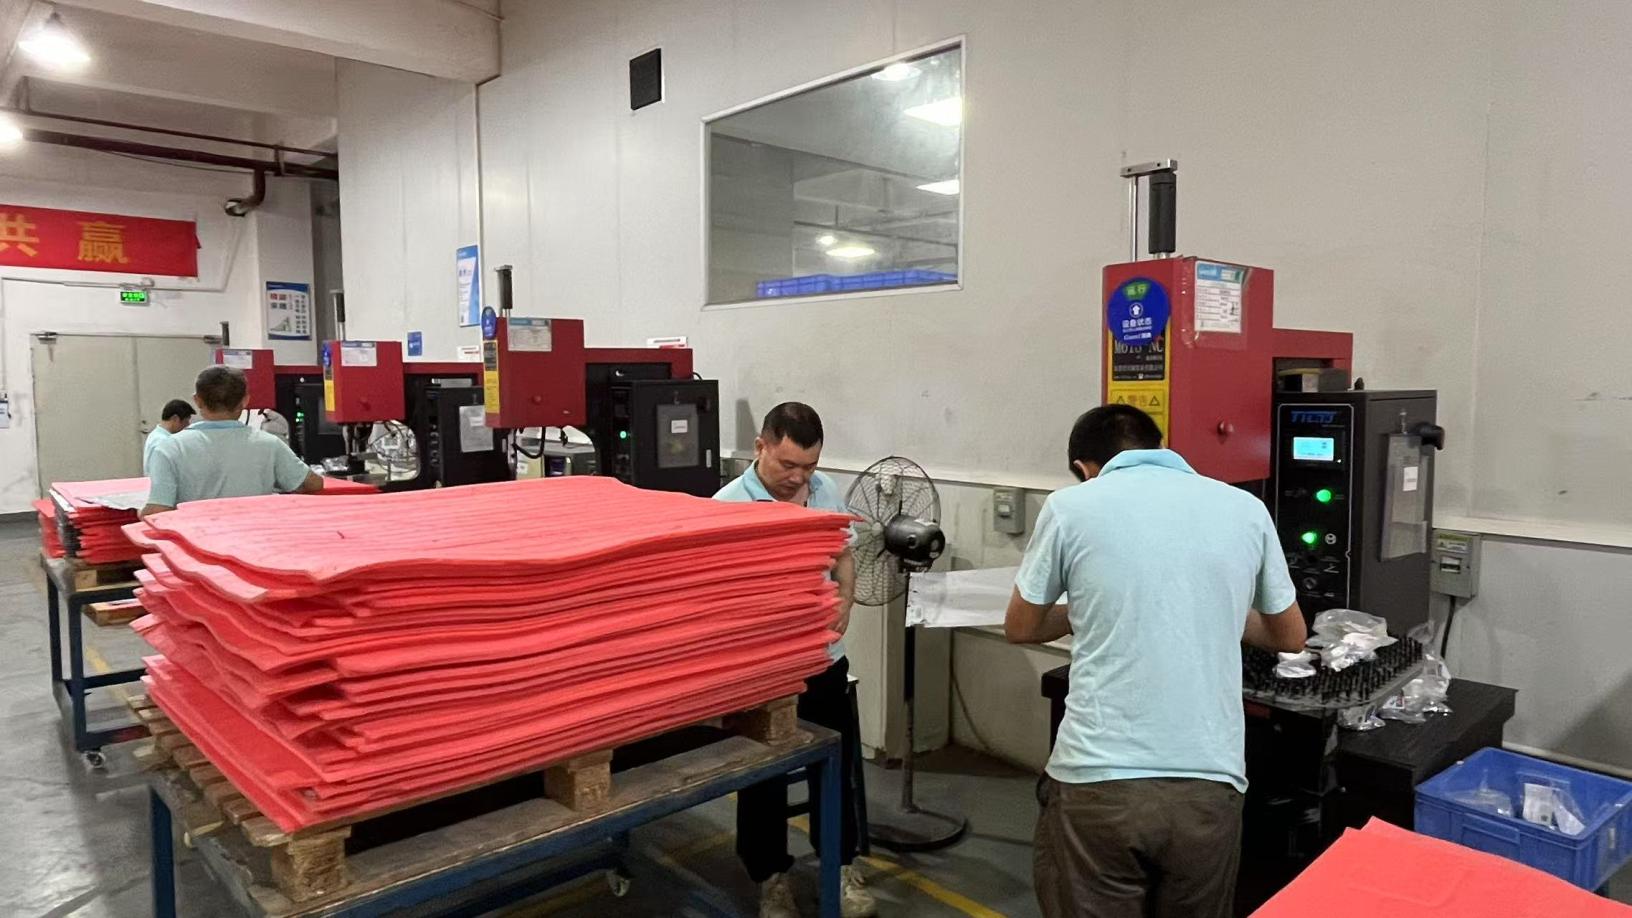
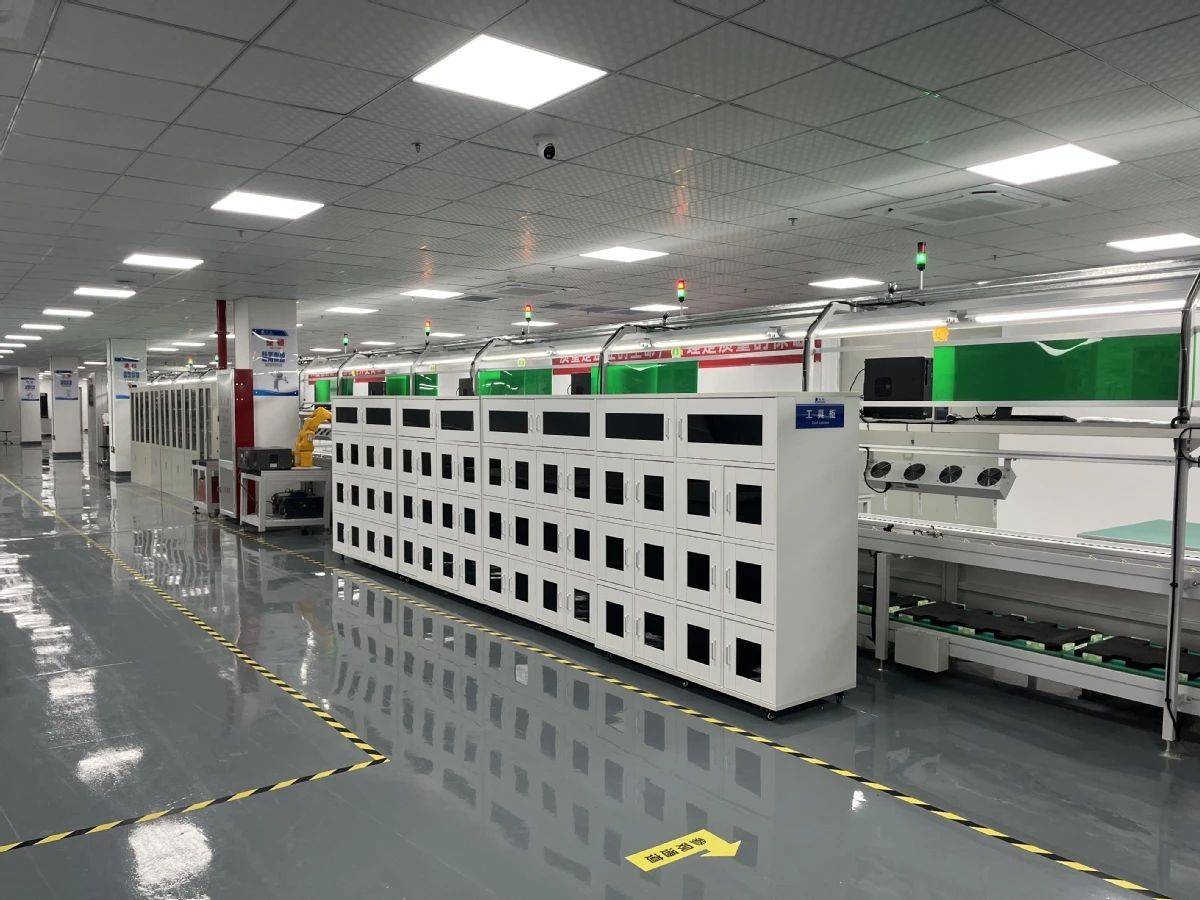
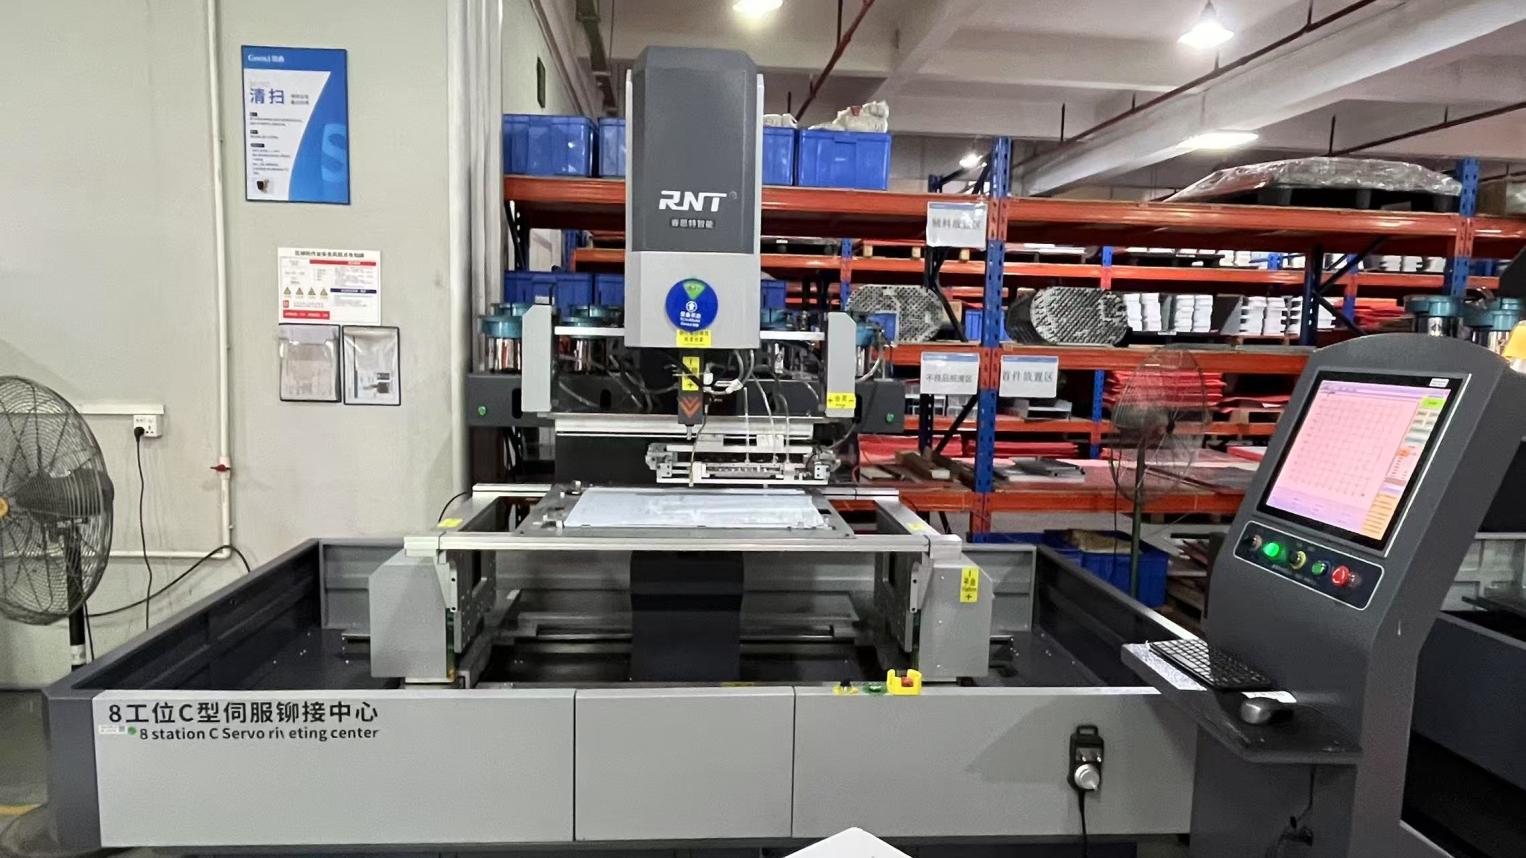
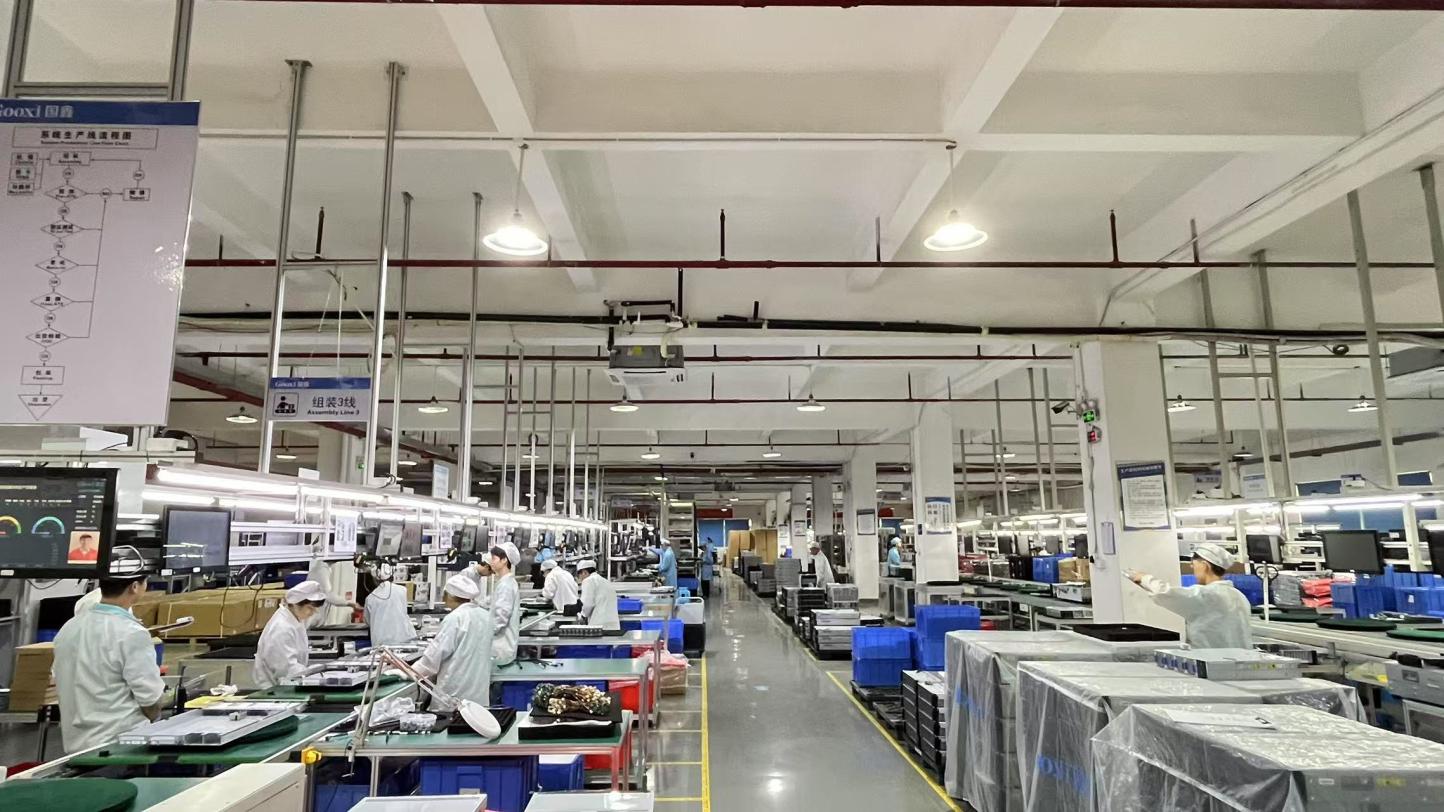
Established in 2016, TensorNova has developed into a trusted supplier in the AI hardware industry with a strong focus on innovation, performance, and customized computing systems. The company operates a modern production facility covering approximately 320㎡, equipped for advanced server assembly, testing, and system integration.
TensorNova records an annual export revenue of approximately $8.5 million, with 6 years of export experience and over 12 years of industry experience in AI computing and server manufacturing.
Quality assurance is strictly implemented through ISO9001-based quality management systems, with product inspection conducted using automated hardware stress testing, thermal performance validation, burn-in testing, and AI workload simulation testing. The company employs around 45 quality control personnel dedicated to ensuring product reliability and stability.
With a strong international trade background, TensorNova serves clients across North America, Europe, Southeast Asia, and the Middle East, with primary markets in the United States, Germany, Singapore, and the United Arab Emirates. TensorNova has established a robust supply chain ecosystem with more than 1,200 global suppliers and strategic component partners, enabling stable production and fast delivery capabilities.
The company primarily serves AI research institutions, cloud computing providers, data centers, enterprise IT departments, and AI startups. Its R&D capabilities are strong, supported by a team of approximately 180 R&D engineers, focusing on GPU server architecture, AI optimization, and high-density computing systems.
TensorNova offers extensive customization options, including GPU configuration customization, chassis design, cooling system optimization (air or liquid cooling), motherboard-level tuning, and AI workload-specific optimization solutions. In the past year, the company successfully launched 320+ new products, including next-generation AI GPU servers, edge computing nodes, and high-density GPU cluster systems. Driven by continuous innovation, TensorNova is committed to delivering reliable, scalable, and high-performance AI computing infrastructure solutions for the global AI industry.
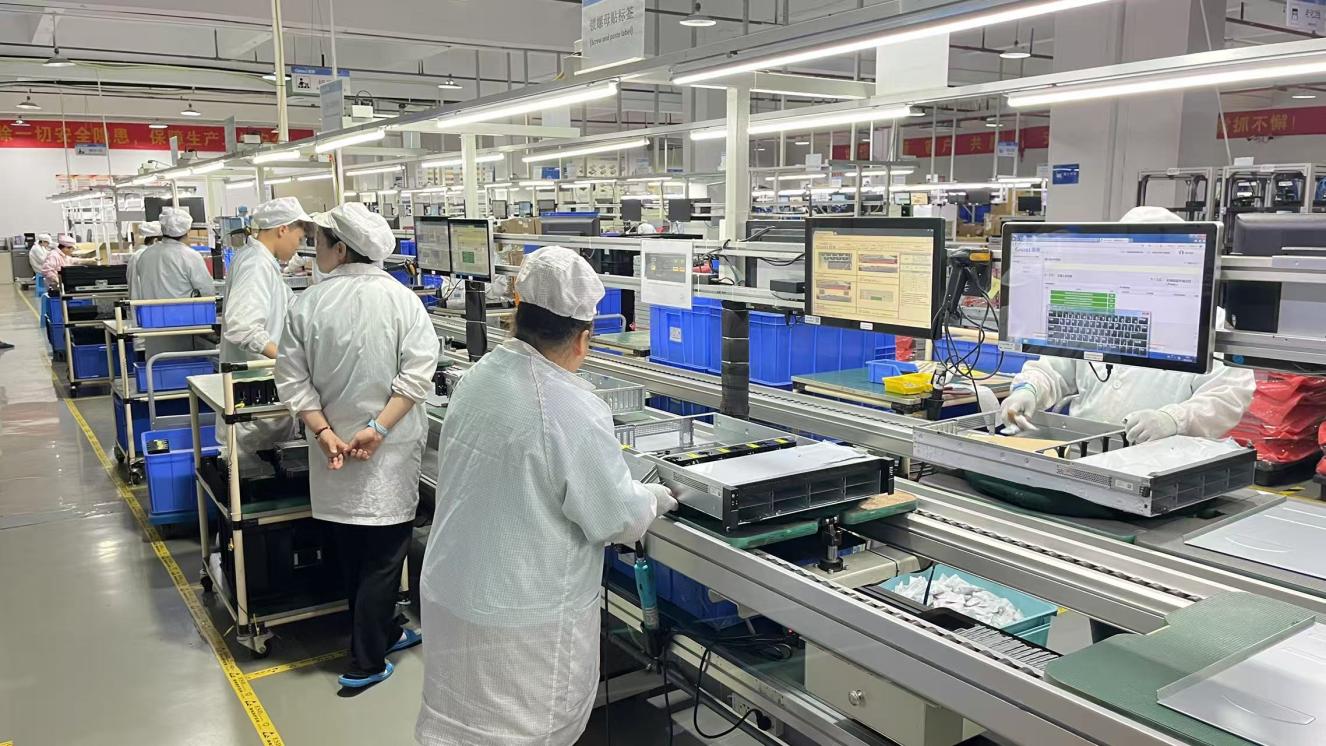
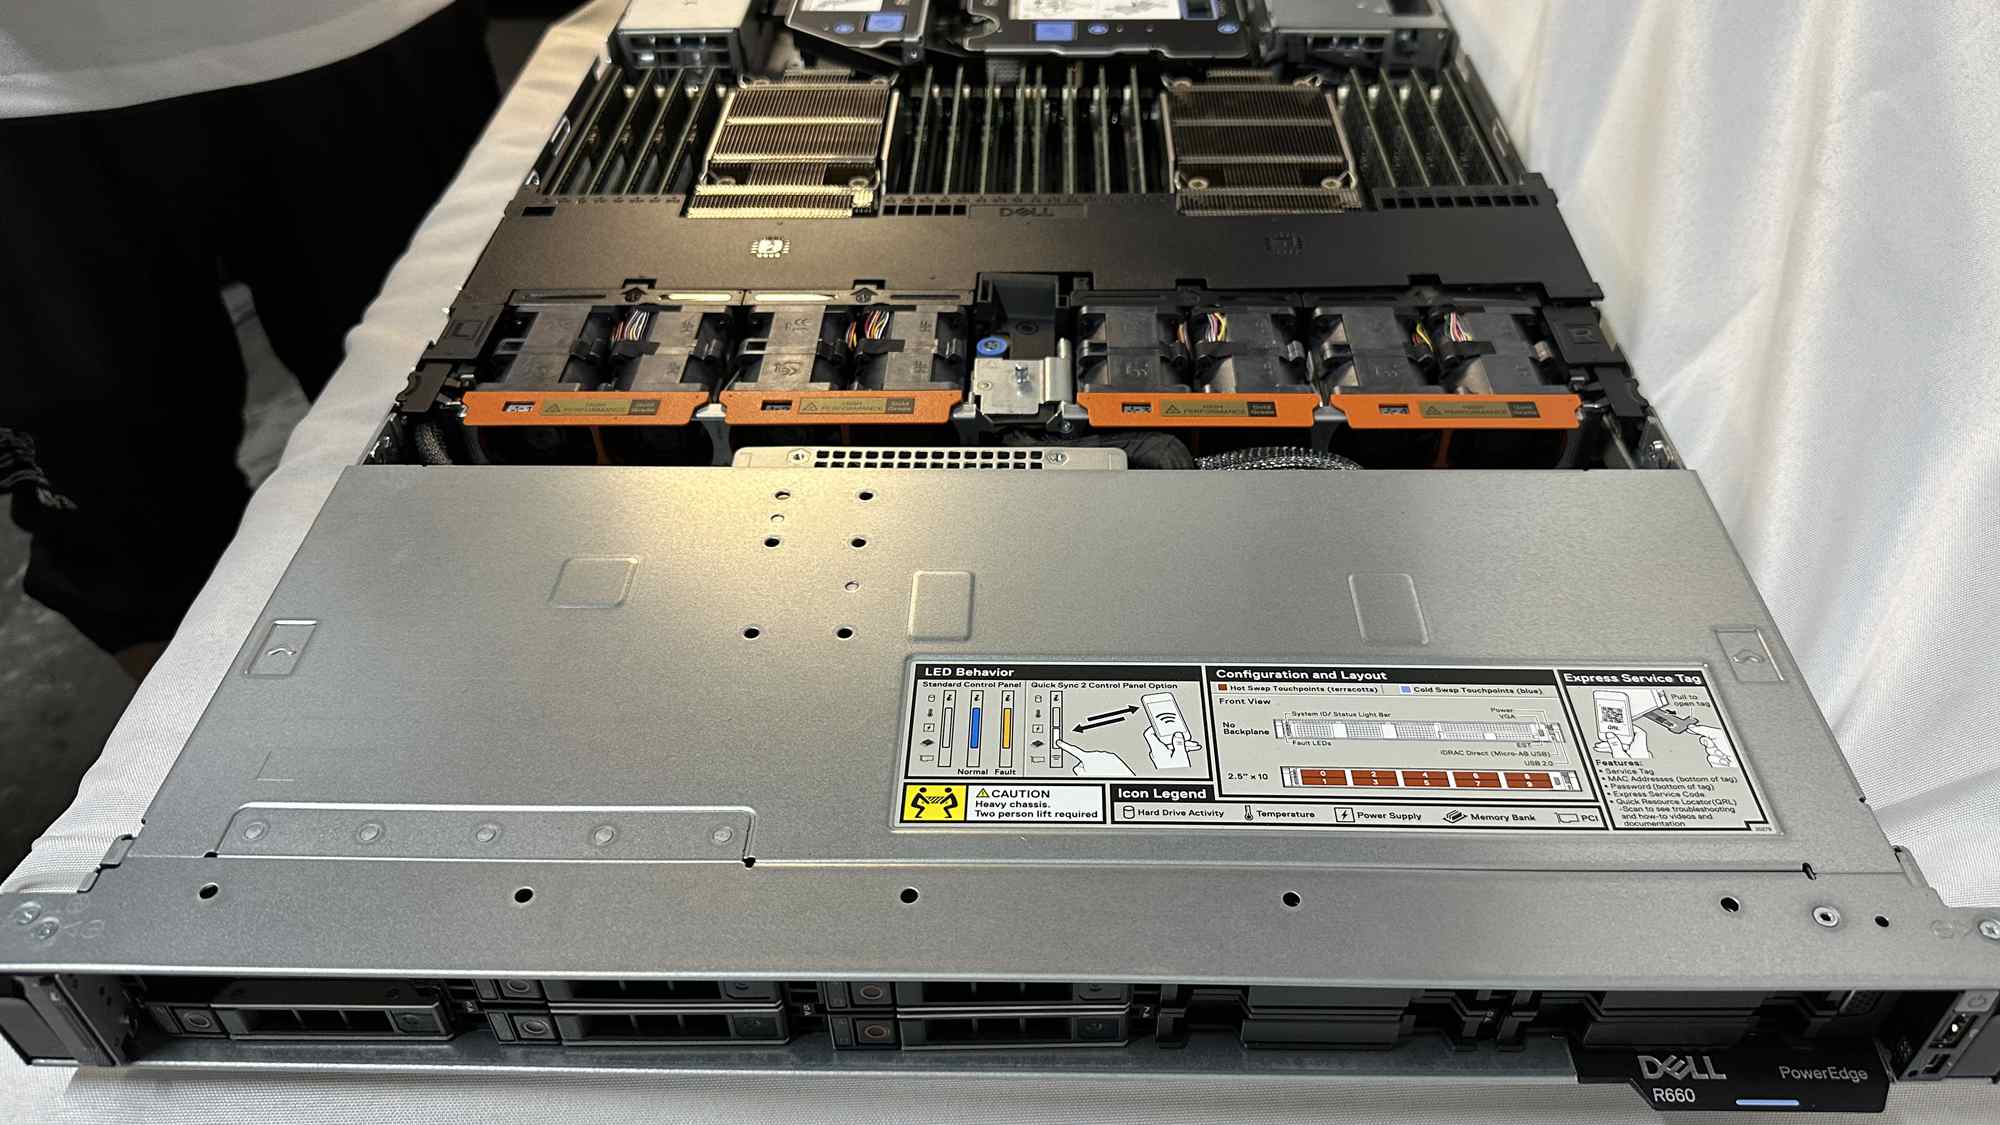
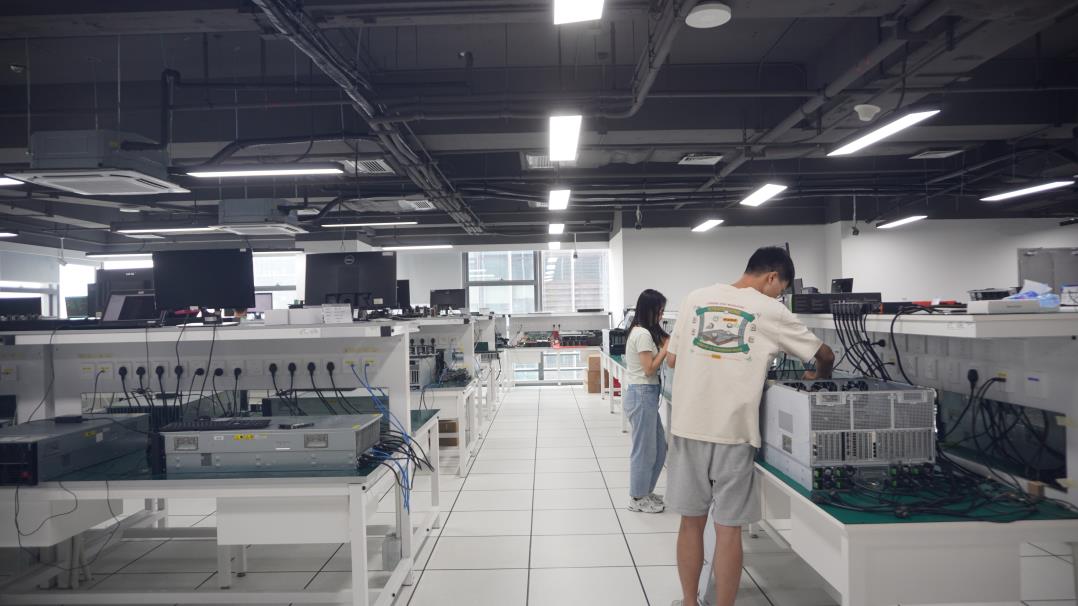
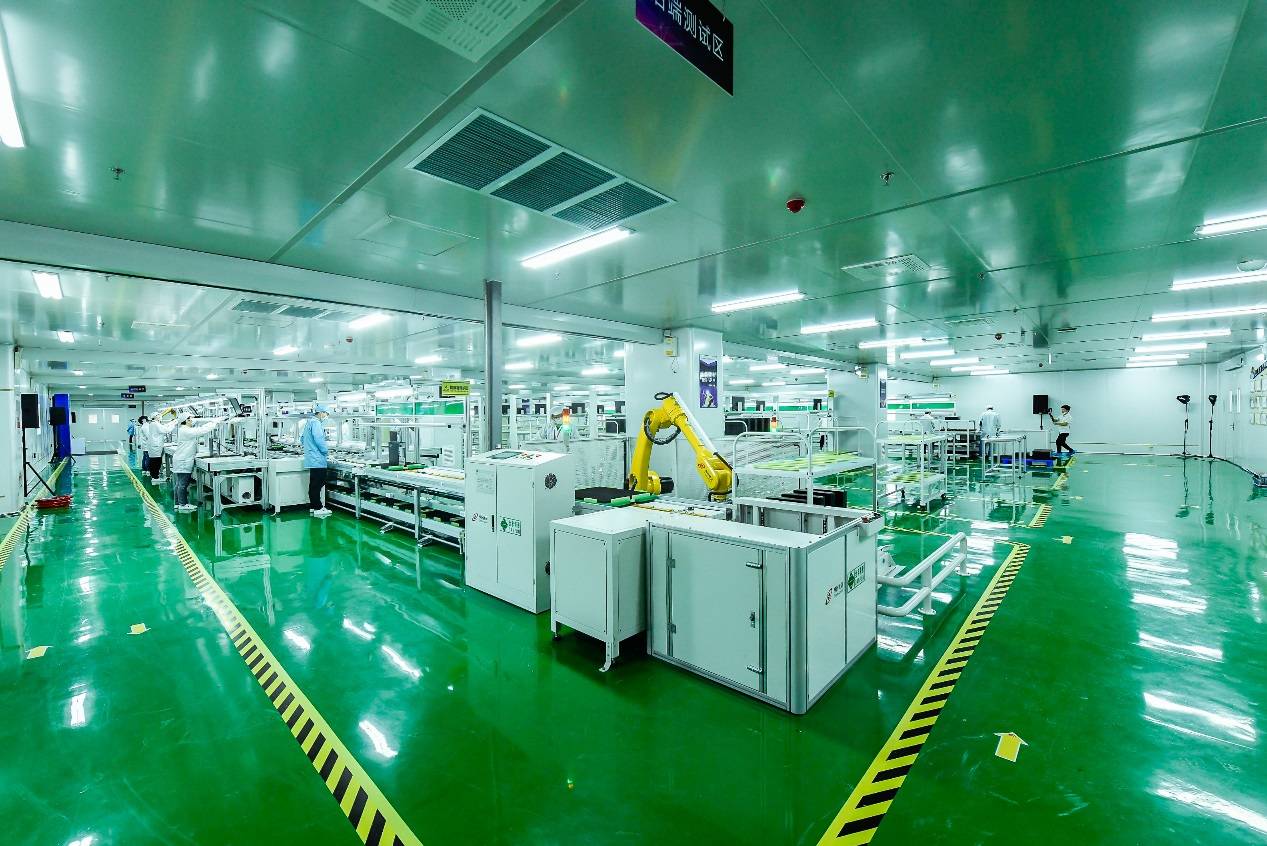
Building an unshakeable hardware disaster recovery foundation requires meticulous engineering across physical compute nodes, ultra-fast interconnects, and non-volatile storage backplanes. As an OEM/ODM provider, TensorNova implements a multi-tier technical roadmap designed for continuous uptime:
| Hardware Category | Primary DR Architecture | RTO / RPO Performance Target | Target Enterprise Application |
|---|---|---|---|
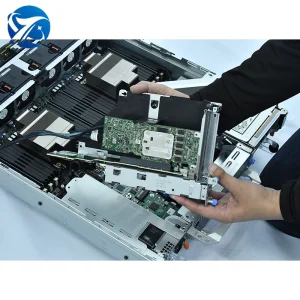
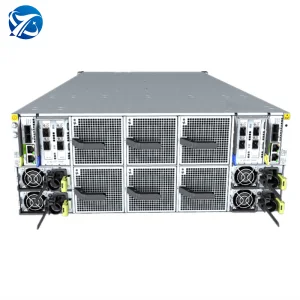
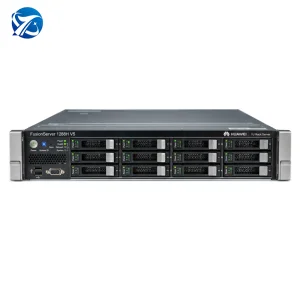
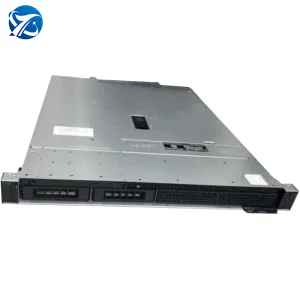
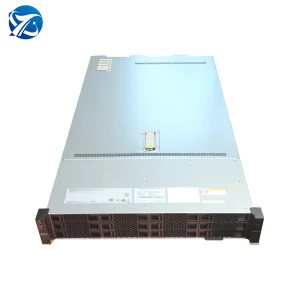
| 1U/2U High-Density Rack Nodes (e.g., PowerEdge R660XS, 1288H V7) | Dual-Socket Intel Xeon / AMD EPYC, Hot-Plug Fan Modules, Hardware RAID 0/1/5/10/60 with Cache Vault | RTO < 15 Seconds RPO = 0 (Synchronous) |
Financial Transaction Processing, Core ERP Databases, Active Directory Master Nodes |
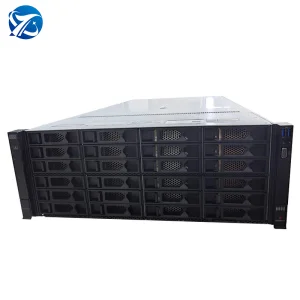
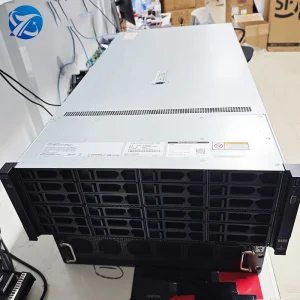
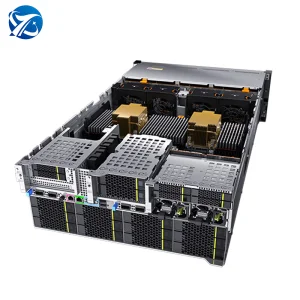
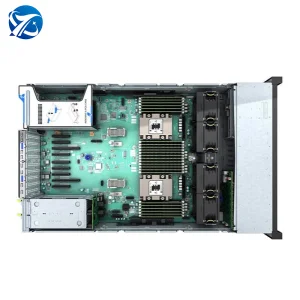
| 4U/8U Multi-Socket & GPU Clusters (e.g., FusionServer 2488H V5, G8600 V7) | 4-Socket / 8-GPU Symmetrical Multi-Processing, Hybrid Liquid-to-Air Cooling, Redundant 2000W+ PSUs | RTO < 3 minutes RPO < 5 seconds |
Deep Learning Model Checkpointing, Real-Time AI Inference Failover, Sovereign Cloud Services |
| NVMe High-Speed Storage Nodes (e.g., Read Intensive SSD Series, NAS Systems) | Dual-Port NVMe PCIe 5.0 drives, PCIe Switch Topology, RDMA over Converged Ethernet (RoCE v2) | RTO Near Instantaneous RPO = 0 |
Cold Storage Repositories, Immutable Snapshot Backup Vaults, Ransomware Shield Storage |
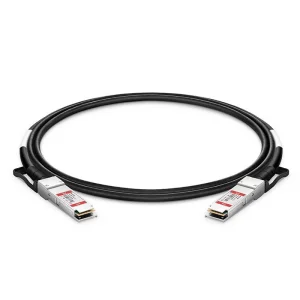
| High-Speed Interconnects (e.g., QSFP+ 10G/40G DAC Cables) | Direct-Attach Copper / Active Optical Cables, Low-Latency Crosspoint Switching, Zero-Frame Loss Architecture | Sub-microsecond latency transfer | Inter-Rack SAN Mirroring, Cluster Heartbeat Synchronization, Storage Target Fabric |
TensorNova's customized OEM/ODM framework allows global technology vendors, managed service providers (MSPs), and cloud architects to configure bespoke disaster recovery units catered directly to localized environment constraints:
Answers to critical questions regarding hardware fault tolerance, OEM customization capabilities, and global server integration.
Explore our full line of GPU acceleration servers, scalable NAS nodes, and high-performance computing platforms for continuous enterprise operations.