TensorNova
Explore our certified enterprise compute nodes, high-density storage chassis, and OEM component replacement stocks designed for low MTTR (Mean Time to Repair) and sustained data center resilience.
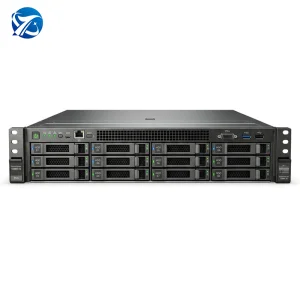
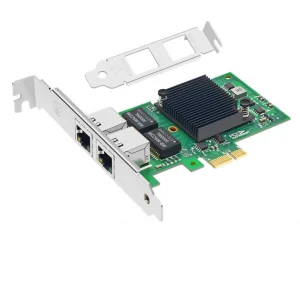
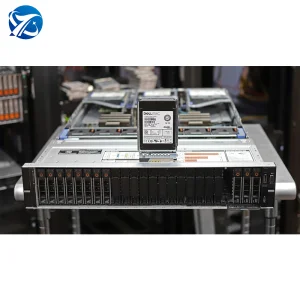
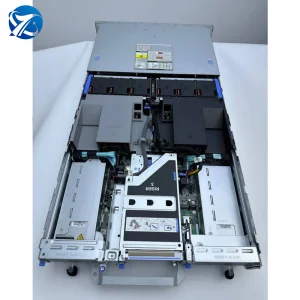
In modern hyper-scale data centers, enterprise IT clusters, and specialized AI computing environments, server hardware uptime directly translates into operational profitability and system integrity. As server architectures evolve toward multi-socket configurations, high-density GPU acceleration, PCIe Gen 5 interconnects, and complex thermal dissipation matrices, maintenance can no longer be treated as a reactive replacement process. It represents a continuous, highly specialized discipline bridging component manufacturing, firmware validation, predictive telemetry, and Third-Party Maintenance (TPM) engineering.
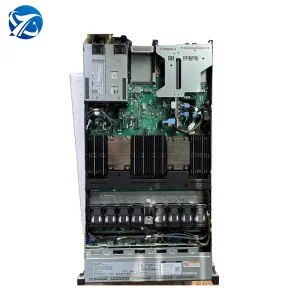
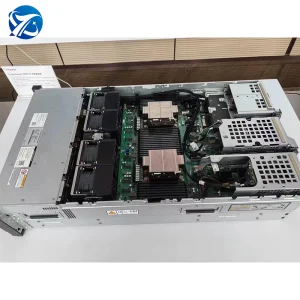
China has emerged as the global epicenter for server hardware manufacturing, OEM assembly, and specialized maintenance component sourcing. As a leading China Wholesale Server Maintenance Manufacturer & Exporter, TensorNova provides end-to-end hardware lifecycle support, replacement Field Replaceable Units (FRUs), server mainboards, power distribution units (PDUs), RAID controllers (e.g., SAS3908 architecture), and custom chassis modifications for international enterprise clients.
Direct access to original component manufacturers (OCMs) for Xeon/EPYC sockets, ECC DDR4/DDR5 RDIMMs, high-speed backplanes, and redundant hot-swappable power supplies (PSUs).
Implementation of Baseboard Management Controller (BMC) telemetry monitoring, IPMI 2.0 validation, and automated microcode updates to isolate silicon degradation prior to failure.
Rapid delivery framework for mission-critical components with certified hardware burn-in testing to guarantee seamless swap-outs without kernel panics or array corruption.
The Pearl River Delta electronics cluster—specifically the Shenzhen hardware technology hub—represents the world's most concentrated, responsive ecosystem for enterprise compute hardware. This geographical advantage enables unmatched speed in component sourcing, customized structural fabrication, and system-level validation.
Leveraging direct relationships with over 1,200 verified tier-1 component vendors, Chinese maintenance manufacturers optimize BOM costs without compromising signal integrity, thermal tolerance, or mean time between failures (MTBF).
Legacy data centers often face hardware obsolescence when Tier-1 OEMs discontinue support for legacy generations (e.g., xFusion V5/V6 or Dell PowerEdge 13G/14G). China's industrial infrastructure maintains dedicated production lines for legacy FRUs, refurbished mainboards, and replacement backplanes.
TensorNova is a professional high-performance AI GPU server manufacturer and enterprise IT infrastructure solution provider based in China. Founded in 2016, TensorNova has grown into a global provider of compute hardware, OEM maintenance solutions, and modular data center systems.
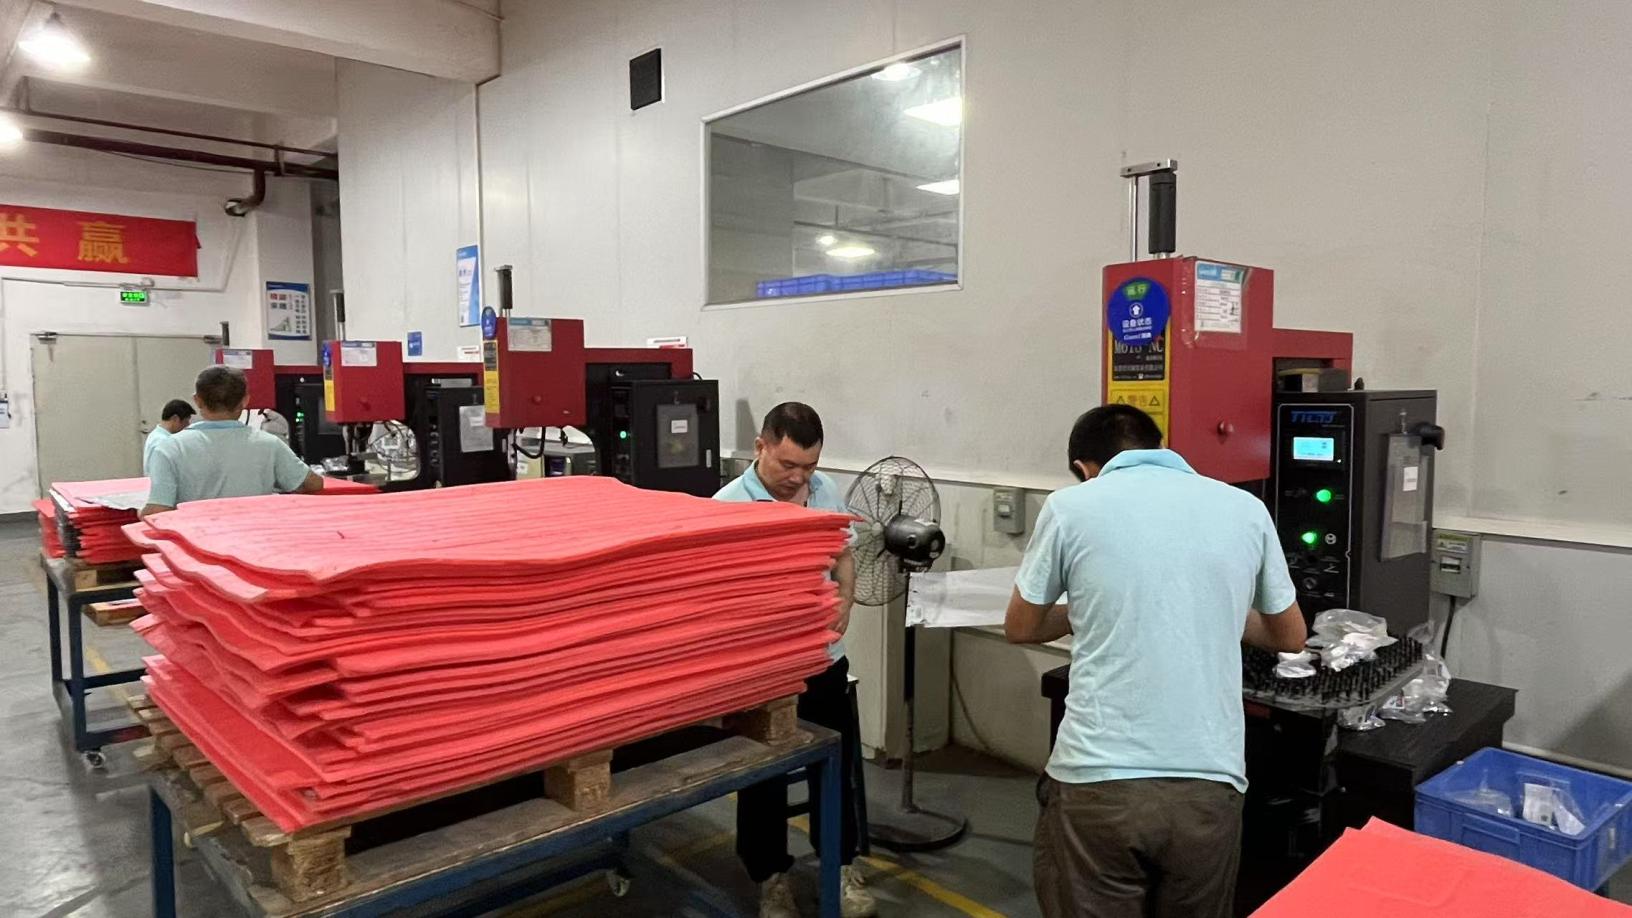
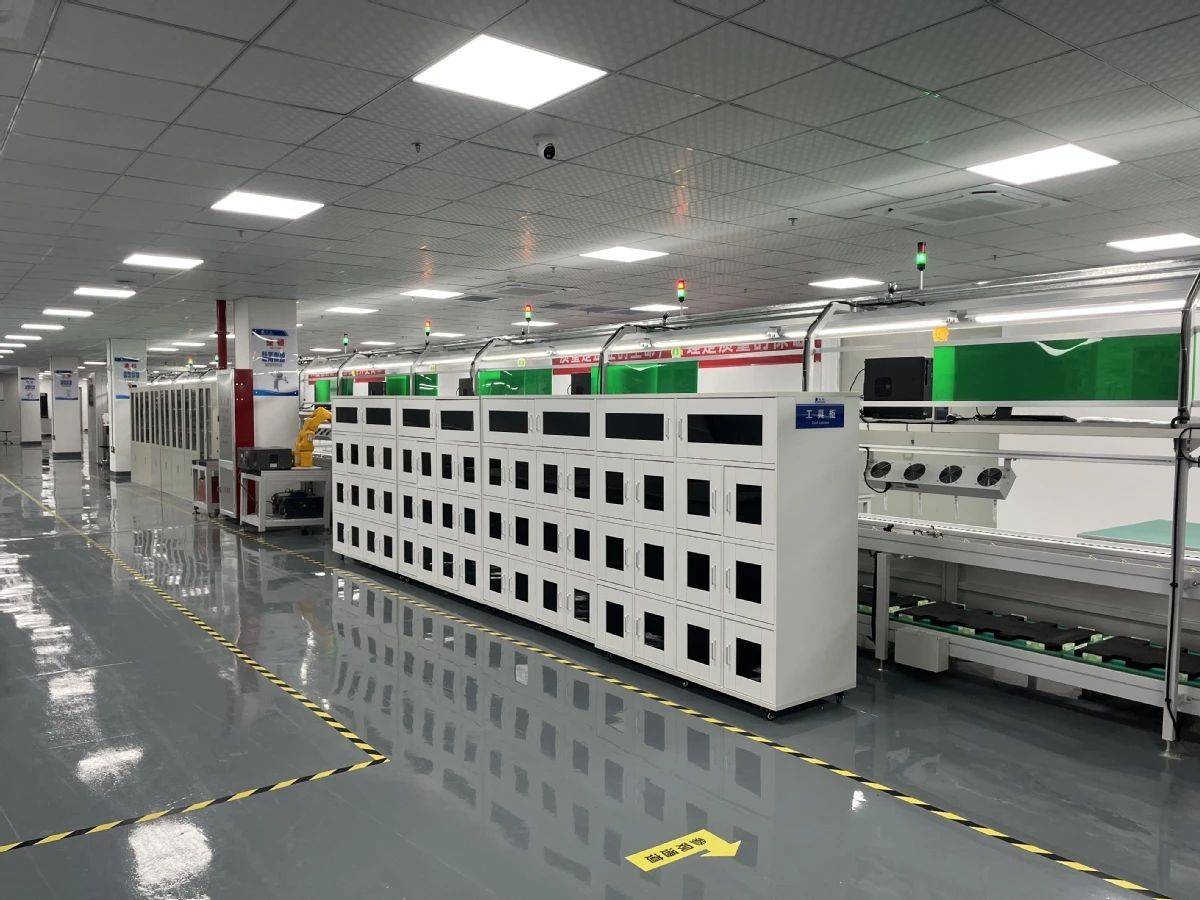
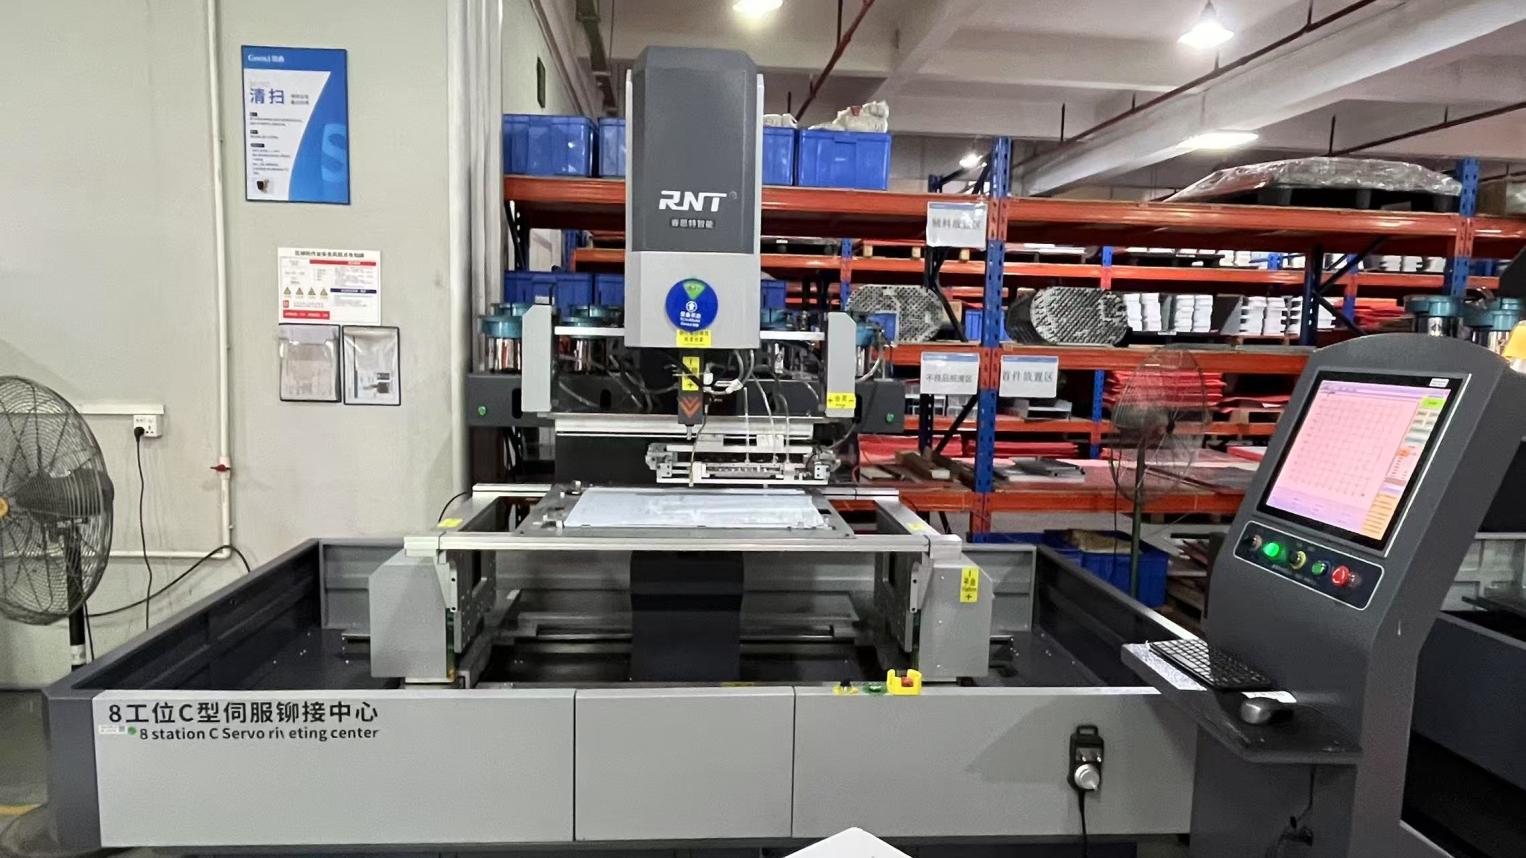
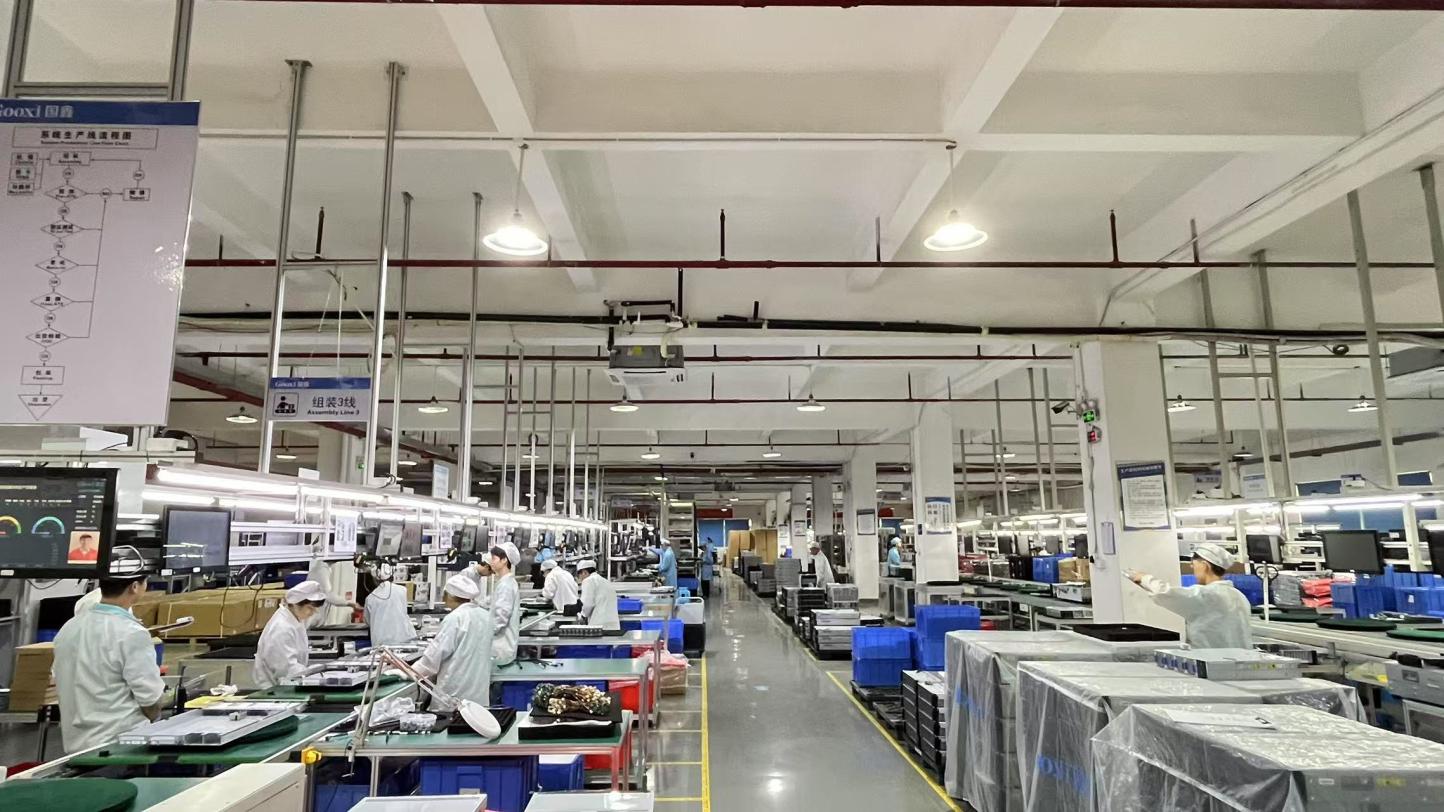
Operating a modern, specialized assembly and validation facility spanning 320㎡, TensorNova enforces strict ISO9001-based quality management systems. Every replacement board, expansion card, and server unit undergoes continuous stress validation, thermal imaging, burn-in testing, and simulated AI cluster workload testing prior to packaging.
Our 45 QC engineers execute 72-hour full-load stress testing (Linpack, Prime95, FurMark) across extreme thermal ranges (0°C to 45°C) to guarantee ZERO DOA (Dead On Arrival) shipments.
Backed by 180 R&D engineers, we offer liquid/air hybrid cooling chassis designs, customized motherboard BIOS/UEFI tuning, and PCIe topology optimization for high-density compute.
With 6 years of international trade operations, TensorNova exports to tier-1 hubs in the United States, Germany, Singapore, United Arab Emirates, and wider North American/European regions.
Global cloud service providers (CSPs), enterprise data centers, AI startups, and financial trading institutions face mounting pressure to balance computing performance with Total Cost of Ownership (TCO). High inflation, hardware component lead times, and supply chain bottlenecks have shifted procurement strategies toward hardware extension and agile wholesale maintenance sourcing.
Direct replacement of failed modules—such as SAS/SATA RAID array cards (e.g., XC470C-M-8i with 4GB cache) or single CPU sockets—avoids the capital expenditure of full rack replacements, achieving up to 70% savings per node.
Standard OEM hardware replacement cycles can take 4 to 8 weeks. Partnering with a China wholesale exporter equipped with vast buffer stocks guarantees express air-freight dispatch, cutting MTTR down to 48-72 hours globally.
Mission-critical legacy applications often depend on specific kernel versions and hardware drivers. Wholesale maintenance hardware guarantees identical component replacements without requiring software stack re-architecting.
Navigating cross-border enterprise hardware deployment requires absolute adherence to international environmental, electrical, and data privacy regulations. TensorNova operates a globally compliant manufacturing and exporting pipeline.
Ensuring strict electromagnetic compatibility (EMC) and low radiation interference across high-frequency 100GbE/400GbE networking environments.
Full restriction of hazardous substances in solder pastes and gold-finger plating, promoting sustainable, recyclable hardware lifecycle disposal.
Secure firmware sanitization protocols for all refurbished or warranty-replaced storage controllers, protecting enterprise data confidentiality.
Compliant hardware-level cryptography, TPM 2.0 security module integration, and secure encrypted SSD/NVMe drive clearing options.
As workload densities surge with LLM training (e.g., DeepSeek, GPT architectures) and high-frequency cloud microservices, server maintenance practices are experiencing fundamental technological shifts:
With TDPs of modern GPUs exceeding 700W and CPUs reaching 350W+, traditional air-cooling fan assemblies are giving way to Direct Liquid Cooling (DLC) and immersion tanks. Maintenance now encompasses dielectric fluid monitoring, quick-disconnect coupling seal replacements, coolant loop flushing, and micro-channel cold plate de-aeration.
Reactive fixing is replaced by AIOps. Machine learning models analyze real-time BMC log feeds (temperature gradients, voltage fluctuations, ECC memory soft error counts) to predict component failure up to 14 days before a fatal system crash occurs.
CXL 2.0/3.0 standards decouple memory from individual server mainboards. Maintenance engineering expands to managing dynamic memory disaggregation, hot-plugging fabric expansion units, and maintaining multi-host controller signal coherence.
Multi-GPU nodes (e.g., xFusion 2288H V7 / G5200 V5) require precise torque application on GPU heat sinks, specialized thermal interface materials (TIMs), and InfiniBand cable testing to avoid micro-burst packet loss.
TensorNova's server maintenance components and customized OEM compute nodes are deployed across mission-critical enterprise environments globally:
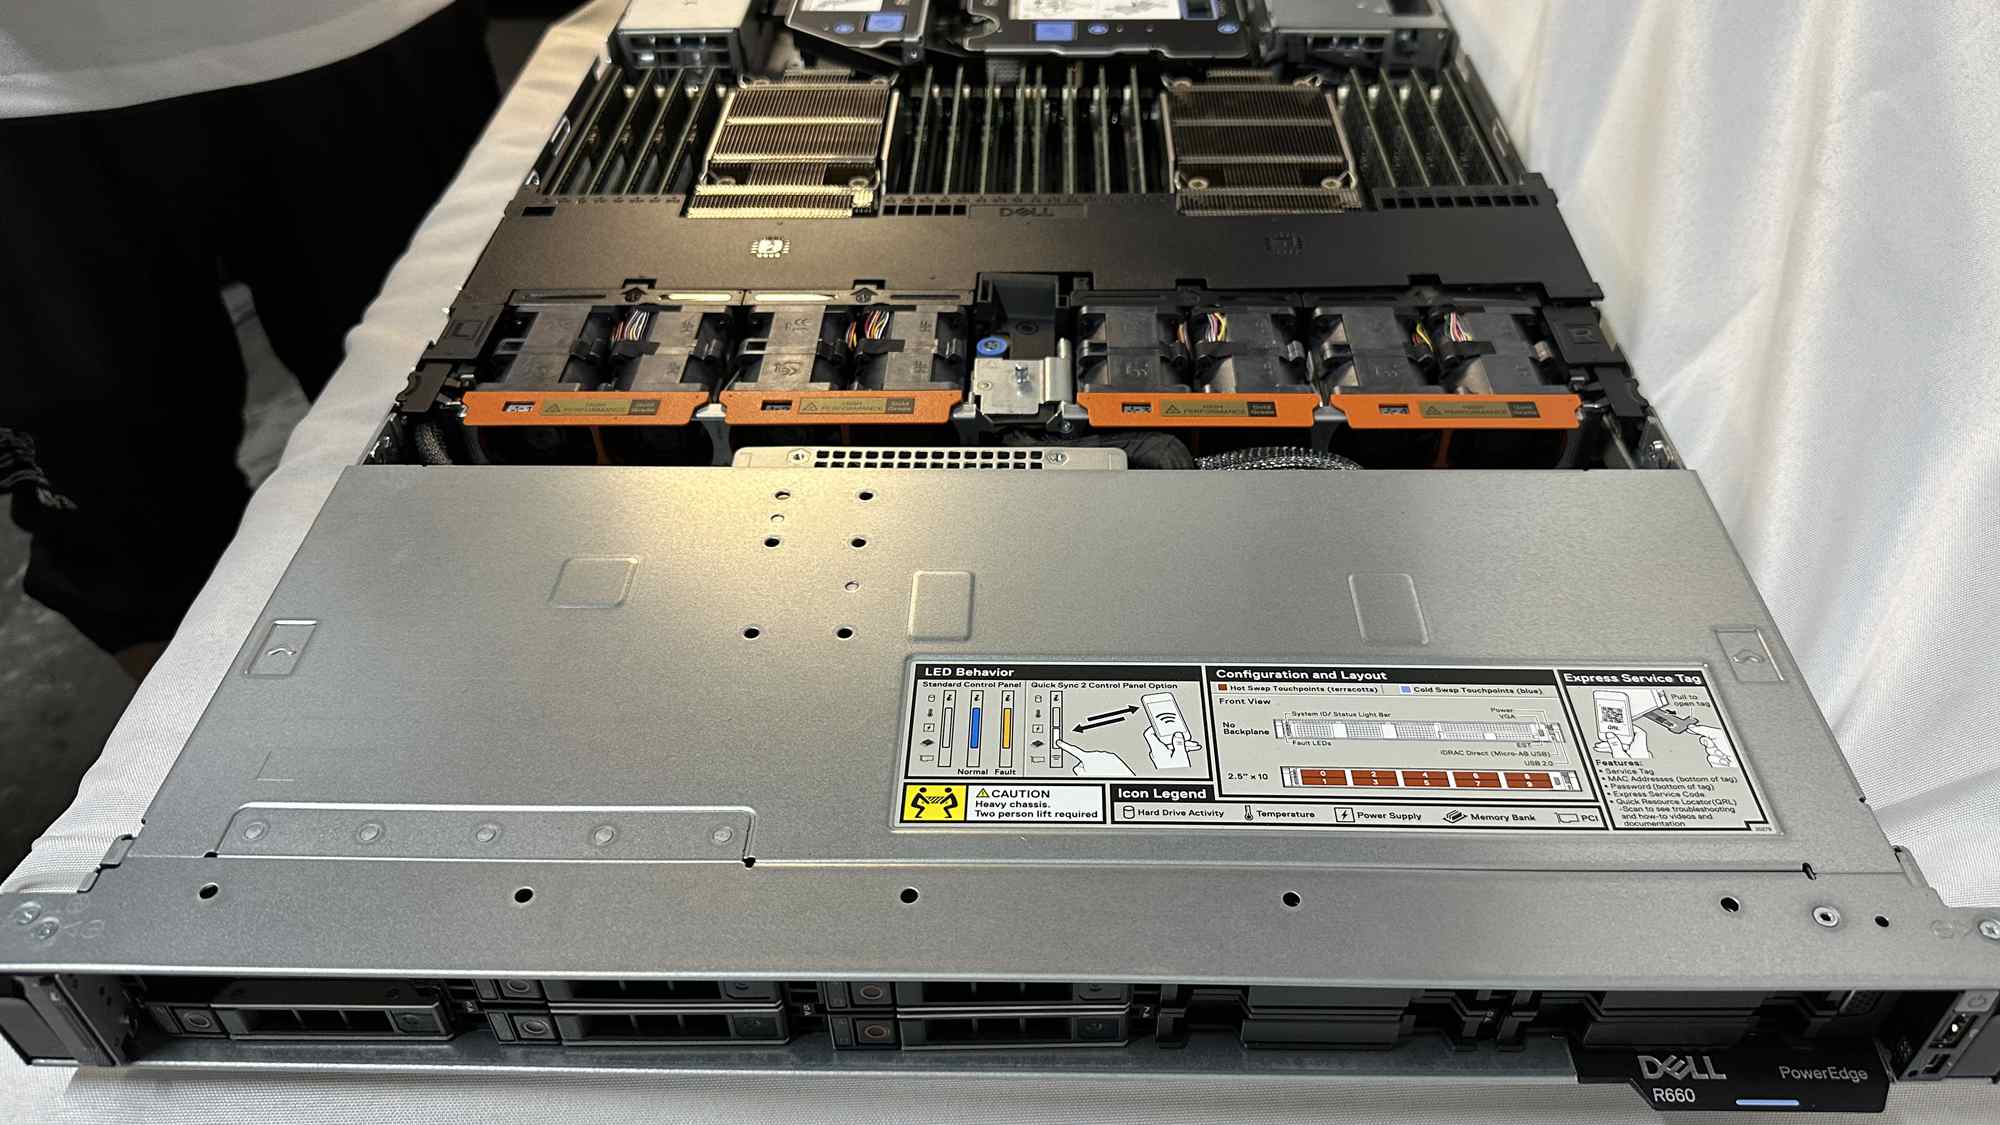
High-density 2U 2-socket rack servers (Dell PowerEdge R750/R760, xFusion 2288H V6/V7) providing steady-state hypervisor performance with 99.999% availability SLAs.
Short-depth, ruggedized server nodes installed at cell towers and regional edge POPs, engineered for harsh thermal operating bands and remote IPMI management.
Ultra-low latency network card replacements, custom overclocked BIOS profiles, and zero-packet-loss RAID card maintenance for real-time transaction processing.
Comprehensive technical answers for data center architects, procurement officers, and system integrators.
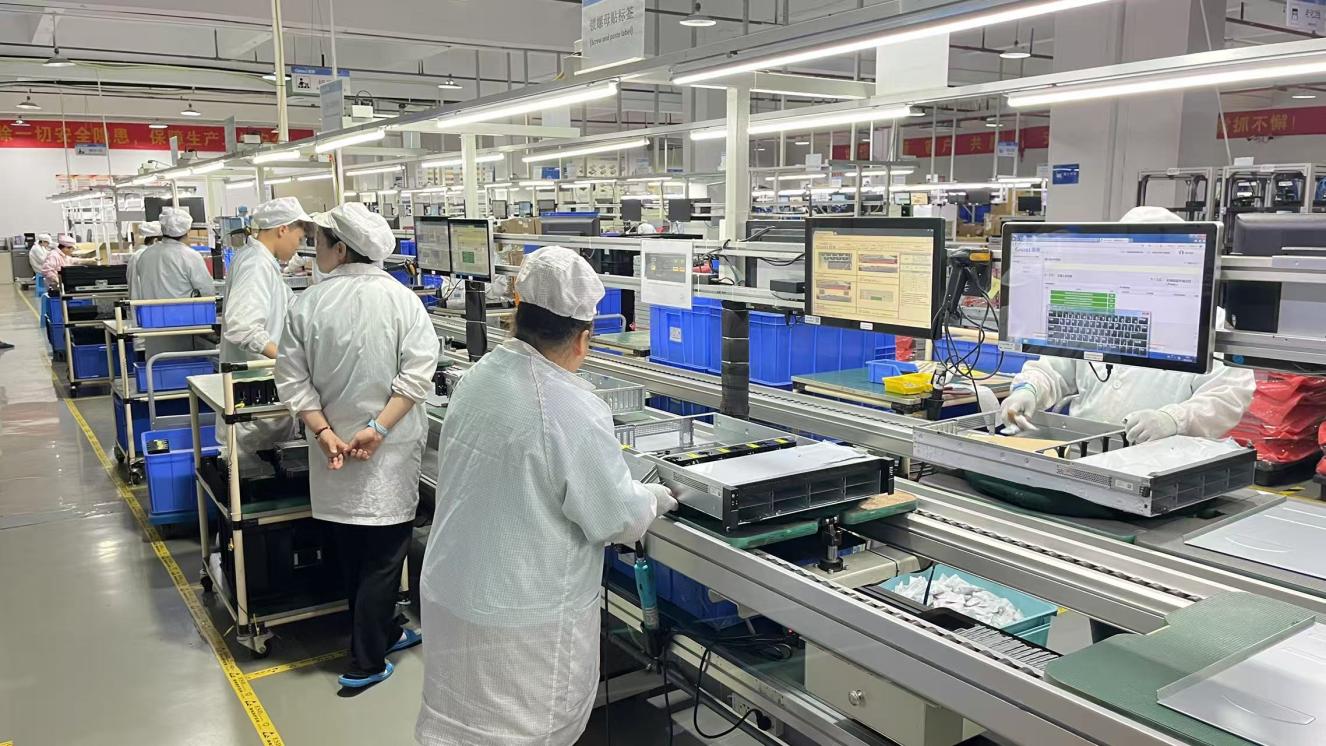
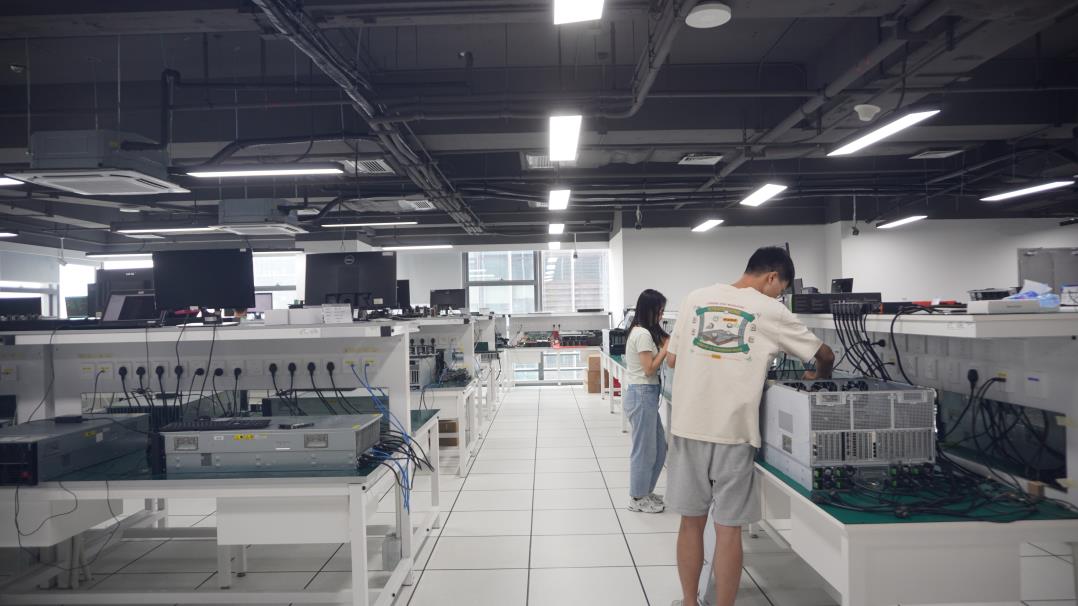
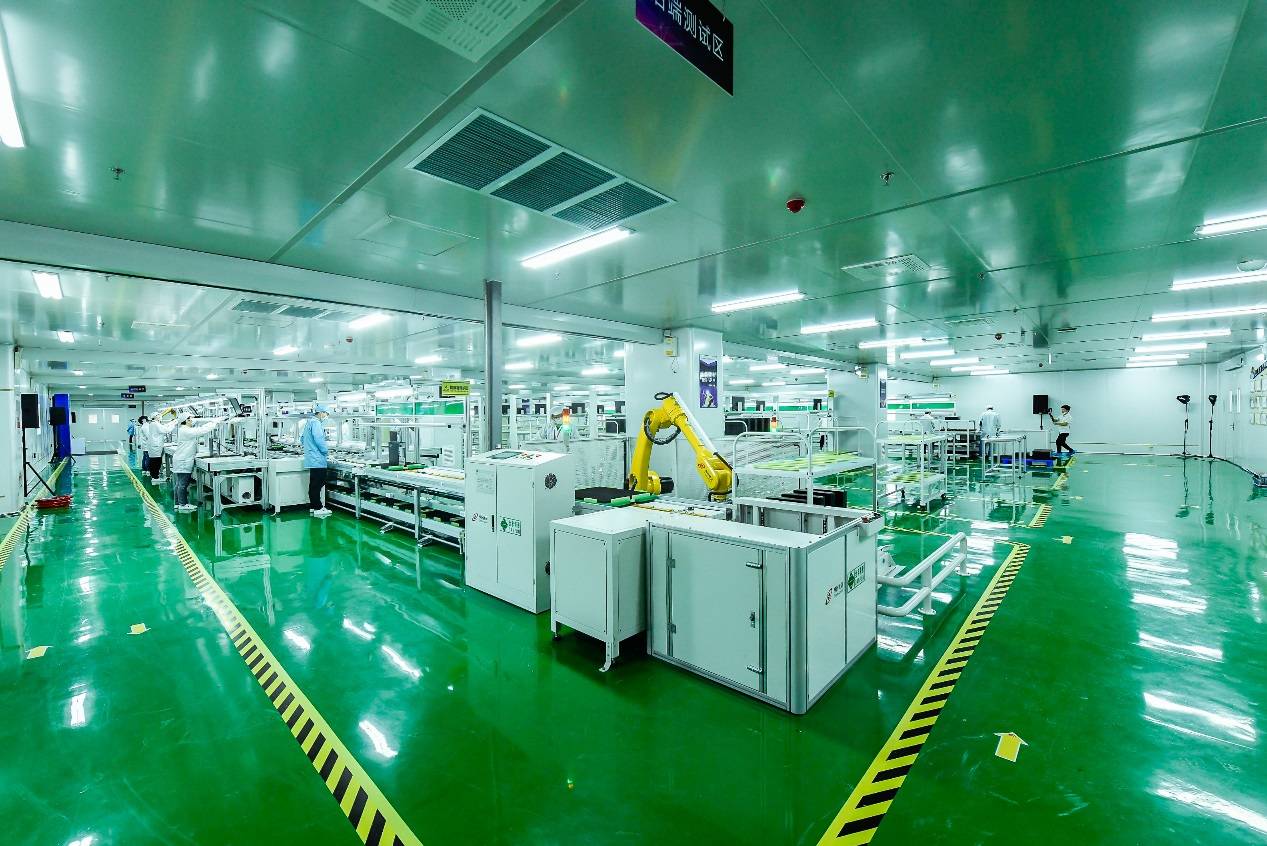
Inside our 320㎡ ISO9001-certified assembly plant, automated diagnostic rigs, and GPU stress testing facility in China.
Browse our full range of enterprise servers, memory modules, and specialized AI infrastructure nodes available for global wholesale export.