TensorNova TensorNova

7 Tips for Choosing an NVIDIA GPU Server Manufacturer

Time:2026-11-02 Author:Liam
0%

Choosing an NVIDIA GPU server manufacturer is not just a matter of comparing processor names or advertised speeds. The right partner must understand how GPUs, CPUs, memory, storage, and networking work together under sustained workloads. A configuration that looks impressive on paper may struggle when several accelerators share power and cooling limits. Details matter. Ask how the manufacturer validates airflow, handles thermal monitoring, and tests systems before shipment.

This guide presents seven practical tips for evaluating potential suppliers. It covers NVIDIA platform compatibility, system design, manufacturing experience, quality checks, support, customization, and transparent pricing. Look for evidence, not broad promises: a sample test report, clear warranty terms, or a specific explanation of how the chassis supports your chosen GPUs can help you assess a claim. Ask who will troubleshoot a failed accelerator and how replacement parts are handled. These questions may feel routine. They are not.

A careful comparison should also reflect your actual work, whether that means AI training, inference, rendering, or scientific computing. Requirements differ, and the largest configuration is not always the best value. Even a detailed checklist has limits; real workloads can reveal issues that a sales conversation cannot. Use these tips to ask better questions, verify important details, and choose a manufacturer whose capabilities match your needs.
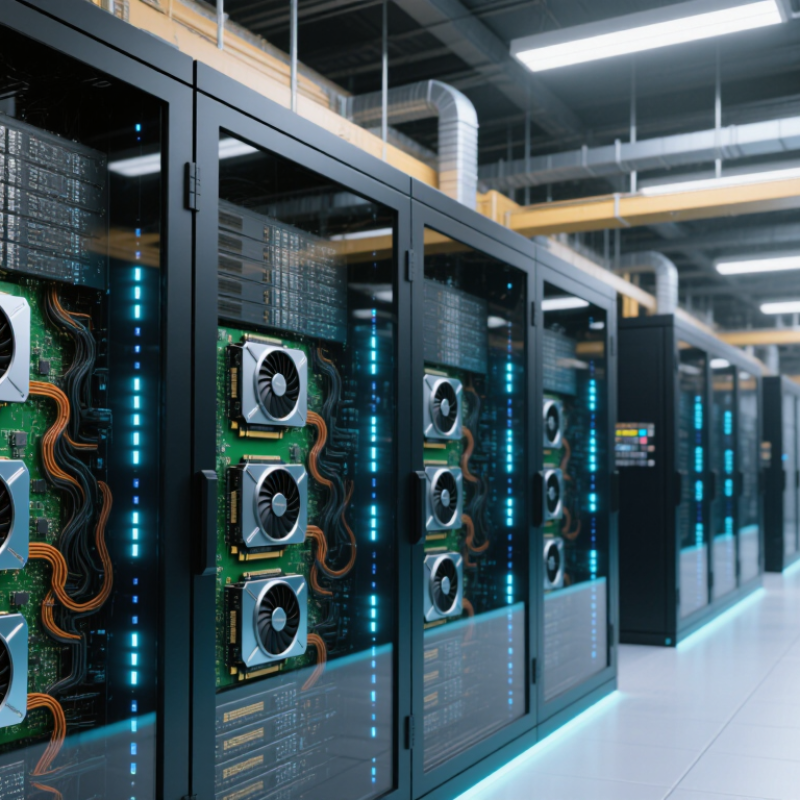
7 Tips for Choosing an NVIDIA GPU Server Manufacturer

Identify Your Workload and NVIDIA GPU Requirements

Before comparing server manufacturers, define the work the GPUs must do. Training large models stresses memory capacity and fast GPU-to-GPU communication. Inference may depend more on response time, concurrent users, and memory bandwidth. Write down model size, input length, expected daily requests, and target precision. Then estimate how many GPUs each workload needs. Measure before you buy.

GPU memory is often the constraint people underestimate. A model may fit on paper but leave too little room for long prompts, larger batches, or growth. Ask manufacturers to explain memory use, interconnect layout, and supported GPU configurations. Request benchmark results for workloads resembling yours, not just peak performance figures. Those figures can mislead. A short test with your model, batch size, and typical input length can expose bottlenecks early.

Also match the server to its operating environment. Sustained GPU loads create substantial heat and power demand, so check rack space, cooling capacity, and electrical limits. Ask how performance changes under continuous load, and whether service access is practical in your facility. Estimates are never perfect; I’d leave some headroom rather than build around an optimistic forecast. A server that handles today’s workload but cannot accommodate a modest increase may become an expensive constraint.

Compare Server Configurations, Scalability, and Compatibility

Choosing a GPU server manufacturer starts with comparing complete configurations, not counting accelerators alone. Ask for the exact GPU model, memory capacity, CPU, system memory, storage, and network interface in each quote. A system with powerful GPUs may still underperform if CPUs cannot feed workloads quickly or storage slows data loading. Heat tells the truth. Request thermal test results and sustained performance figures, not just peak specifications.

Scalability depends on more than empty rack space. Confirm available power, cooling capacity, rack depth, and whether future GPU additions require replacing the chassis or power supplies. Ask how expansion affects networking and service access. Small details matter. A practical manufacturer should explain upgrade limits clearly and provide configuration options for expected workload growth. Leave room for uncertainty: demand forecasts can be wrong, and buying maximum capacity upfront may waste budget.

Compatibility needs the same careful review. Check that server firmware, operating system, drivers, and workload software support the proposed GPUs and interconnects. Verify slot layout, power connectors, and network bandwidth against your deployment plan. Request a tested bill of materials and written validation details. Check the details. A polished specification sheet is useful, but it cannot replace testing with representative workloads. One easy mistake is focusing on headline performance; I would revisit that assumption before approving a purchase.

7 Tips for Choosing an NVIDIA GPU Server Manufacturer

Compare server configurations, scalability, and compatibility using a practical evaluation framework.

Suggested evaluation weights add up to 100% and are a planning guide, not a market survey. Adjust them for your workload, budget, and deployment requirements. Check GPU, CPU, memory, networking, power, cooling, and software compatibility against the exact server configuration.

Assess Manufacturer Expertise and NVIDIA Technology Support

A capable server manufacturer should explain how its engineering team works with the GPU platform, not just list supported components. Ask for a written compatibility matrix covering accelerators, processors, memory, network adapters, and operating system versions. Check whether technicians can diagnose driver, firmware, and interconnect issues together. That matters. A mismatch between firmware and drivers can cause instability that looks like a faulty GPU.

Request a sample deployment plan for your workload, such as model training or scientific computing. It should identify power limits, cooling requirements, rack airflow, and expected performance tests. Ask how systems are validated under sustained load, not only during a short factory check. Ask for evidence. Useful support includes clear escalation paths, tested driver updates, and practical guidance for replacing a failed component.

Clarify who owns complex cases when several parts interact. Vague answers are a warning sign. I would still verify support claims with a technical call; documentation can be polished while real response times vary. A small pilot can reveal gaps before a full purchase.

Evaluate Reliability, Security, and Quality Assurance

A dependable NVIDIA GPU server manufacturer should show how reliability is measured, not just promise high uptime. Ask for failure-rate data, warranty terms, and typical repair turnaround times. Details matter. Request references from customers running comparable workloads, then ask what happened during an actual hardware fault. A useful answer describes diagnosis, replacement parts, and communication—not only the final fix. Check whether systems are tested under sustained GPU load, with temperatures and power use recorded. A short demonstration is helpful, but it cannot replace evidence from longer validation runs.

Security and quality assurance deserve the same scrutiny. Ask how firmware versions are tracked, updates are verified, and access to production systems is restricted. Component traceability should connect each server’s serial number to its key parts and test records. Ask for sample burn-in reports, acceptance criteria, and documentation of how failed units are handled. A checklist alone is not enough. Certifications may support a review, but they do not prove every process is followed consistently. I would also ask how the manufacturer reports vulnerabilities and manages corrective updates. No supplier is flawless; clear records and candid answers about exceptions are more credible than claims of zero risk.

Review Pricing, Warranties, and Long-Term Service

A low purchase price can hide expensive gaps. Compare the full three-to-five-year cost: servers, support, replacement parts, shipping, and power requirements. Uptime Institute’s 2024 Global Data Center Survey reported that 54% of respondents’ most recent significant outages cost over $100,000. That figure makes response terms worth checking before you sign.

Tip 1: Request itemized quotes for the same GPU, memory, storage, and network configuration. Tip 2: Read warranty exclusions closely. Confirm coverage length, response times, replacement procedures, and whether labor or shipping costs extra. A “next business day” promise may not mean a replacement arrives the next day. Ask for the exact service-level terms in writing.

Tip 3: Test the long-term service plan. Ask whether spare parts are stocked near your site and how firmware updates are handled. Request references from customers running similar workloads, then ask about actual repair times. A spreadsheet helps, but it cannot predict every failure. I would still leave some budget for surprises. GPU systems change quickly, and even a careful forecast can miss future support needs.

7 Tips for Choosing an NVIDIA GPU Server Manufacturer - Review Pricing, Warranties, and Long-Term Service

Tip What to Compare Evidence to Request Decision Check
1. Compare complete system pricing Review the full configuration, including GPUs, CPUs, memory, storage, networking, power supplies, cooling, and required software or services. An itemized quote with configuration details, shipping, taxes, installation, and any recurring fees listed separately. Compare systems with equivalent components and service scope, not just the headline price.
2. Confirm the configuration fits the workload Check GPU memory, CPU capacity, system memory, storage throughput, network bandwidth, and the number of supported accelerators. A written configuration sheet and workload-specific performance or compatibility information. Verify that the proposed system meets your application requirements and power, space, and cooling limits.
3. Read the warranty terms carefully Compare warranty duration, covered components, repair or replacement process, labor coverage, and exclusions. The complete warranty document, including start date, return procedures, and responsibility for shipping costs. Confirm that coverage applies to the complete system and clarify how separately sourced components are handled.
4. Evaluate long-term technical support Check support hours, contact channels, escalation process, and whether support covers hardware, firmware, and system integration. Written support terms that define coverage hours, issue priorities, and any response-time commitments. Make sure support availability matches the operating schedule and criticality of your workloads.
5. Check spare-parts and repair arrangements Ask how replacement parts are sourced, where repairs take place, and how service is handled if a component fails. Details on repair locations, parts availability practices, return authorization, and on-site service options, if offered. Understand the likely service process and who coordinates each step before placing an order.
6. Verify compatibility and validation Review operating-system and driver support, firmware management, networking, storage, and application requirements. Compatibility documentation, system test procedures, and validation results for the proposed configuration. Request confirmation that the exact configuration—not only a similar system—has been checked for your intended environment.
7. Assess upgrade and lifecycle planning Consider component upgrade options, maintenance planning, documentation, and the process for future configuration changes. A documented upgrade path, service contact details, and information about configuration records and maintenance support. Choose a service plan that can support the system throughout its expected operational life.

FAQS

What should I define before choosing a GPU server?

Record model size, input length, daily request volume, and target precision. Estimate GPU needs for each workload. Measure first.

Why does GPU memory capacity matter?

A model may fit but leave little room for long prompts or larger batches. Ask for memory-use estimates and interconnect details. Small margins matter.

Are peak performance figures enough to compare servers?

No. Request benchmarks using workloads close to yours, including typical batch sizes and input lengths. A short test can reveal bottlenecks, though it is not the whole story.

What facility limits should I check?

Confirm rack space, cooling capacity, and electrical limits. Ask how performance changes during continuous GPU use. Leave some headroom; forecasts can be wrong.

How can I assess reliability claims?

Request failure-rate data, warranty terms, and repair turnaround estimates. Ask customers with similar workloads about a real hardware fault. Details matter.

What should a useful fault-response explanation include?

Look for clear steps covering diagnosis, replacement parts, and communication. Ask how service access works in your facility. Perfect answers are unlikely.

What security and firmware processes should I ask about?

Ask how firmware versions are tracked, updates verified, and production access restricted. Also ask how vulnerabilities and corrective updates are reported. Records help.

How can I review quality assurance?

Request burn-in reports, acceptance criteria, and records linking server serial numbers to components and tests. Ask how failed units are handled. Check exceptions, too.

Conclusion

Choosing the right nvidia gpu server manufacturer starts with understanding your workload, whether it involves AI training, data analysis, or other intensive computing tasks. Define the processing power, memory, storage, and networking you need, then compare server configurations for performance, expandability, and compatibility with your existing infrastructure. A well-matched system can support current projects while leaving room to grow.

Look beyond specifications and assess the manufacturer’s technical expertise, ability to support relevant GPU technologies, and approach to reliability, security, and quality testing. Also compare total costs, warranty terms, maintenance options, and the availability of long-term technical support. Considering these factors together can help you select a dependable partner and a server solution suited to both your immediate requirements and future plans.
Liam

Liam

Liam is a dedicated marketing professional with a profound expertise in the industry, where he excels at highlighting the unique advantages of our core products. With a keen understanding of market trends and consumer needs, Liam frequently updates our company’s professional blog, providing......